TEL:+86 132 6656 7067


AI scale-up networking is the high-bandwidth, low-latency interconnect architecture used to connect GPUs and other accelerators within a tightly coupled computing domain. Its purpose is to allow multiple processors to communicate efficiently and operate together as a larger computing system.
Unlike AI scale-out networking, which connects independent servers across racks, scale-up networking focuses on communication between accelerators inside a server, across a rack-scale system or within another closely integrated compute domain.
As AI models become larger and workloads require increasing numbers of GPUs, the communication bandwidth between accelerators becomes an important part of system performance. Technologies such as NVLink and other accelerator interconnects are designed specifically for these high-speed GPU-to-GPU communication requirements.
1. What Is AI Scale-Up Networking?
AI scale-up networking connects multiple GPUs or accelerators through a high-performance interconnect so they can exchange data at very high bandwidth and low latency.
The architecture is designed for tightly coupled workloads where processors need to communicate frequently during computation.
Instead of treating each GPU as an isolated network endpoint, scale-up networking aims to create a highly connected accelerator domain.
2. What Does Scale-Up Mean?
Scale-up means increasing the computing capability of a single tightly coupled system by connecting more processors or accelerators within that system.
In AI computing, this commonly means connecting multiple GPUs so that they can cooperate efficiently on the same workload.
The exact boundary of a scale-up domain depends on the system architecture and interconnect technology.
3. Scale-Up vs Scale-Out Networking
| Feature | Scale-Up | Scale-Out |
|---|---|---|
| Main Purpose | Connect tightly coupled accelerators | Connect independent compute servers |
| Typical Scope | Server, rack or accelerator domain | Multiple servers and racks |
| Main Traffic | GPU-to-GPU communication | Server-to-server communication |
| Latency Requirement | Extremely low | Low and predictable |
| Bandwidth | Extremely high per accelerator | High aggregate fabric bandwidth |
| Typical Technologies | NVLink and accelerator-specific interconnects | Ethernet/RoCE and InfiniBand |
4. Why Is Scale-Up Networking Important?
Large AI workloads cannot always run efficiently on a single GPU.
When a model or workload is distributed across multiple accelerators, those accelerators need to exchange information continuously.
Slow communication can leave computing resources waiting for data, reducing the effective utilization of the accelerator system.
5. GPU-to-GPU Communication
GPU-to-GPU communication is the central requirement of scale-up networking.
GPUs may exchange model parameters, activations, gradients and intermediate results during AI training and inference.
The interconnect must provide sufficient bandwidth and low enough latency to prevent communication from becoming the dominant part of workload execution time.
6. GPU Memory Communication
AI accelerators rely heavily on high-bandwidth memory such as HBM.
When workloads span multiple GPUs, data may need to move from the memory associated with one accelerator to another accelerator.
The efficiency of this communication depends on the accelerator interconnect, memory architecture and software stack.
7. What Is GPU Scale-Up?
GPU scale-up is the process of connecting multiple GPUs into a tightly integrated computing domain.
The GPUs remain separate processors, but the interconnect allows them to communicate much more efficiently than conventional external networking interfaces are designed to provide.
This architecture is particularly useful for workloads with frequent accelerator-to-accelerator communication.
8. What Is a Scale-Up Fabric?
A scale-up fabric is the communication network that connects accelerators within the scale-up domain.
It can include accelerator links, switches, cables, optical or electrical interconnects and the associated software.
The fabric is normally optimized for high bandwidth, low latency and efficient collective communication.
9. NVLink as a Scale-Up Network
NVLink is an example of a purpose-built scale-up networking technology for AI and accelerated computing.
It is designed to provide high-bandwidth GPU-to-GPU communication and can use NVLink Switch technology to connect multiple GPUs into a larger high-performance domain.
Current NVIDIA platforms use NVLink as a dedicated scale-up fabric, while technologies such as InfiniBand and Ethernet are used for scale-out networking.
10. NVLink vs Ethernet for Scale-Up
| Category | NVLink-Style Scale-Up | Conventional Ethernet |
|---|---|---|
| Primary Role | Accelerator scale-up | General networking and scale-out |
| Communication | High-speed accelerator-to-accelerator | Packet-based network communication |
| Latency | Designed for very low latency | Depends on network architecture |
| Bandwidth Density | Very high within accelerator domain | Scales through network ports and switches |
| Network Scope | Tightly coupled compute domain | Servers, racks and larger networks |
11. Is Scale-Up the Same as NVLink?
No.
Scale-up networking is an architectural concept, while NVLink is one technology used to implement a high-performance scale-up fabric.
Other accelerator vendors can use different interconnect technologies to provide similar scale-up functionality.
12. AI Scale-Up Network Topology
A scale-up network can use direct GPU-to-GPU connections, switch-based fabrics or a combination of both.
A switch-based architecture allows a larger number of accelerators to communicate through a common fabric while maintaining high aggregate bandwidth.
The exact topology depends on the accelerator platform and system design.
13. All-to-All Connectivity
All-to-all connectivity means that each accelerator can communicate with other accelerators through the scale-up fabric.
This is useful for workloads involving collective operations and frequent communication among many GPUs.
A well-designed all-to-all fabric can provide more predictable communication characteristics across the accelerator domain.
14. What Is All-Reduce?
All-reduce is a collective communication operation that combines information from multiple accelerators and distributes the resulting data back to the participating accelerators.
It is commonly used during distributed AI training for synchronization.
The performance of all-reduce depends heavily on both the interconnect and the communication software.
15. What Is All-Gather?
All-gather collects data from multiple accelerators and makes the combined data available to every participant.
This communication pattern can create large amounts of traffic across a scale-up fabric.
High-bandwidth interconnects help reduce the time required to complete such operations.
16. What Is Reduce-Scatter?
Reduce-scatter combines data across accelerators and distributes different portions of the result among the participating devices.
It is another important collective operation used by distributed AI workloads.
Scale-up fabrics are designed to handle these high-volume communication patterns efficiently.
17. Why Do Collective Operations Matter?
AI training and inference frequently use collective communication to coordinate work among accelerators.
Because many accelerators can participate simultaneously, collective operations can generate extremely high communication demand.
The scale-up network therefore has a direct effect on how quickly the distributed computation can proceed.
18. Scale-Up Bandwidth
Bandwidth is one of the most important performance metrics in a scale-up network.
High bandwidth allows large quantities of data to move between accelerators without creating a persistent communication bottleneck.
As GPU computing performance continues to increase, the required interconnect bandwidth also increases.
19. Scale-Up Latency
Latency measures the time required to transfer information between communicating processors.
Scale-up networks generally require very low latency because GPUs can exchange data at extremely high frequency during parallel computation.
Reducing communication latency can help minimize synchronization delays.
20. Bandwidth vs Latency in Scale-Up Networking
| Metric | Meaning | Why It Matters |
|---|---|---|
| Bandwidth | Amount of data transferred per unit of time | Supports large data transfers |
| Latency | Time required to complete communication | Reduces synchronization delay |
| Jitter | Variation in communication delay | Improves predictability |
| Packet Rate | Number of packets processed per unit of time | Supports frequent small communications |
21. Why Predictable Latency Matters
Distributed AI workloads often synchronize many accelerators at the same time.
If one communication path is significantly slower than the others, some accelerators may need to wait before continuing the next stage of computation.
Predictable latency can therefore be important in addition to low average latency.
22. Scale-Up Network Memory Semantics
Some accelerator interconnects provide memory-oriented communication capabilities that go beyond traditional packet networking.
This can enable efficient data movement between accelerator memory spaces and support tightly coupled computing models.
The exact memory semantics depend on the interconnect technology and accelerator architecture.
23. Scale-Up Networking and HBM
High-bandwidth memory provides very large local memory bandwidth for GPUs and other accelerators.
However, when an AI workload spans multiple GPUs, local HBM bandwidth alone is not sufficient. The accelerators must also move data across the interconnect.
Scale-up networking therefore complements high-bandwidth accelerator memory.
24. GPU Memory Bandwidth vs Network Bandwidth
Memory bandwidth describes how quickly an accelerator accesses its local memory, while interconnect bandwidth describes how quickly data moves between accelerators.
Both are important to distributed AI performance.
An application with heavy cross-GPU communication can be limited by interconnect bandwidth even when local memory bandwidth is very high.
25. Scale-Up Networking and AI Training
During distributed training, GPUs repeatedly exchange information as the model is updated.
Operations such as gradient synchronization and collective communication can generate significant traffic.
A high-bandwidth scale-up fabric helps reduce the communication time associated with these operations.
26. Scale-Up Networking and AI Inference
AI inference can also require communication among multiple GPUs.
This is particularly relevant to large language models, mixture-of-experts architectures and other workloads where model execution is distributed across accelerators.
Efficient scale-up communication can reduce the overhead associated with moving intermediate data among GPUs.
27. Scale-Up Networking and Mixture-of-Experts
Mixture-of-Experts models distribute different experts across accelerator resources.
Input tokens may need to move between GPUs depending on which experts process them.
This can produce intensive GPU-to-GPU traffic and make high-bandwidth all-to-all communication particularly important.
28. Scale-Up Networking and Large Language Models
Large language models can contain very large numbers of parameters and may require multiple accelerators for training or inference.
Parallel execution techniques distribute different parts of the workload across GPUs.
Scale-up interconnects help these GPUs exchange the information needed for coordinated execution.
29. Tensor Parallelism
Tensor parallelism divides operations across multiple accelerators.
Because portions of the same computation can execute on different GPUs, tensor-parallel workloads can generate frequent communication between accelerators.
Fast scale-up networking is therefore important for maintaining efficient tensor-parallel execution.
30. Pipeline Parallelism
Pipeline parallelism divides a model into stages that are assigned to different accelerators or groups of accelerators.
Data and intermediate results move between stages as the workload progresses.
The communication requirements differ from tensor parallelism but still depend on efficient interconnects.
31. Data Parallelism vs Scale-Up
Data parallelism can distribute portions of a workload across multiple GPUs or servers.
When the devices are within a tightly coupled system, scale-up networking can accelerate their communication.
When the devices are distributed across separate servers, scale-out networking becomes more important.
32. Scale-Up Communication Inside a Server
Inside a multi-GPU server, accelerators may communicate through dedicated high-speed interconnects.
The physical connection can use short electrical paths, specialized connectors or other high-bandwidth technologies.
The goal is to provide much higher communication performance than a conventional external network interface is designed to offer.
33. Scale-Up Communication Across a Rack
Modern rack-scale AI systems can contain many accelerators that need to communicate as a tightly coupled domain.
Scale-up switching technology can connect these accelerators while maintaining high aggregate bandwidth.
This creates a rack-scale computing domain that is larger than a conventional single server.
34. Rack-Scale AI Systems
Rack-scale AI systems combine multiple servers or accelerator platforms with high-speed networking, memory, storage and power infrastructure.
Scale-up networking provides communication among accelerators, while other networking layers can connect the rack to the wider data center.
35. Scale-Up vs Rack Networking
Rack networking and scale-up networking are not necessarily the same.
A rack can contain both scale-up and scale-out communication paths.
The scale-up fabric handles tightly coupled accelerator communication, while the scale-out fabric connects servers and other systems across the larger cluster.
36. Scale-Up vs Scale-Out in an AI Cluster
| Network Layer | Scale-Up | Scale-Out |
|---|---|---|
| Connection | GPU-to-GPU or accelerator-to-accelerator | Server-to-server |
| Domain | Tightly coupled accelerator domain | Cluster-wide fabric |
| Primary Goal | Maximum local communication performance | Cluster scalability |
| Typical Technology | NVLink and similar accelerator fabrics | InfiniBand and Ethernet/RoCE |
| Optical Role | Depends on system architecture | Very important for inter-rack links |
37. Scale-Up Networking and PCIe
PCIe is a general-purpose high-speed interconnect used to connect processors, accelerators and peripheral devices.
Dedicated accelerator scale-up fabrics can provide communication capabilities optimized specifically for GPU-to-GPU traffic.
PCIe and scale-up networking can therefore coexist within the same AI system.
38. Scale-Up Networking and CPU-to-GPU Communication
AI systems can also require high-speed communication between CPUs and GPUs.
The architecture may use PCIe, CXL or accelerator-specific technologies depending on the platform.
Scale-up networking is primarily focused on tightly coupled accelerator communication, but the broader system includes CPU-to-accelerator paths as well.
39. Scale-Up Networking and CXL
CXL is a high-speed interconnect technology designed around PCIe-based infrastructure and enhanced memory and device communication capabilities.
CXL and accelerator-specific fabrics can serve different purposes within an AI platform.
The exact role of CXL depends on the memory, accelerator and system architecture.
40. Scale-Up Networking and Switches
A scale-up switch allows many accelerators to connect through a shared high-performance switching fabric.
This can expand the scale-up domain beyond the number of direct point-to-point accelerator connections that would otherwise be practical.
Switch architecture therefore becomes an important part of large AI systems.
41. Scale-Up Switch vs Ethernet Switch
| Feature | Scale-Up Switch | Ethernet Switch |
|---|---|---|
| Primary Purpose | Accelerator interconnect | General network connectivity |
| Connected Devices | GPUs and accelerators | Servers, NICs and network devices |
| Traffic | Highly synchronized GPU communication | Packet-based network traffic |
| Optimization | Bandwidth and low latency for accelerators | Network scalability and packet forwarding |
42. Scale-Up Fabric and All-to-All Traffic
Many AI communication patterns require multiple accelerators to exchange information simultaneously.
An all-to-all capable fabric can provide direct or switched paths among a large number of participating accelerators.
The ability to handle these traffic patterns efficiently is important for communication-intensive workloads.
43. Scale-Up Networking and In-Network Computing
Some advanced scale-up fabrics can perform certain collective operations within the network fabric itself.
Offloading operations such as reductions can reduce the amount of work that individual GPUs must perform.
This can improve collective communication efficiency when supported by the hardware and software stack.
44. Scale-Up Networking and NCCL
NCCL is a communication library designed to support collective operations between GPUs.
It can select communication paths and algorithms according to the available GPU topology and networking hardware.
The software layer is therefore an important part of scale-up performance.
45. Scale-Up Networking and Software Co-Design
High-performance AI networking depends on both hardware and software.
The accelerator, interconnect, switch, communication library, driver and workload framework must work together to use the available bandwidth efficiently.
Optimizing only one part of the stack may not provide the same benefit as coordinated system design.
46. Scale-Up Networking and Topology Awareness
Communication software can take the physical topology of the accelerator fabric into account when selecting communication paths.
Some GPU pairs may have direct connections, while others may communicate through one or more switches.
Topology-aware communication can help distribute traffic efficiently.
47. Scale-Up Networking and Bandwidth Utilization
High theoretical bandwidth does not automatically result in equivalent application-level performance.
Real performance depends on communication patterns, topology, software efficiency, data size, synchronization and contention.
Effective bandwidth measures how much useful application data can actually be transferred through the fabric.
48. Scale-Up Networking and Communication Overhead
Communication overhead includes the time and resources required to move data between accelerators.
When communication represents a large fraction of total workload execution time, improving the scale-up network can have a significant impact on system efficiency.
49. Scale-Up Networking and GPU Utilization
GPU utilization can decrease when accelerators spend significant time waiting for data or synchronization.
A high-performance scale-up network can reduce communication delays and help accelerators spend more time performing useful computation.
50. Scale-Up Networking and System Efficiency
System efficiency depends on the balance between computation, memory access and communication.
A powerful GPU system can still be limited by communication if the interconnect cannot keep up with the workload.
Scale-up networking therefore needs to scale alongside GPU compute performance.
51. Scale-Up Networking and Power Consumption
High-speed interconnects consume power through transmitters, receivers, switches, drivers, SerDes and other components.
As the number of GPUs increases, the aggregate interconnect power can become significant.
Power efficiency is therefore an important consideration when designing a large scale-up fabric.
52. Scale-Up Networking and Thermal Design
Power consumption becomes heat, which must be removed from the system.
Dense AI platforms can generate substantial thermal loads from GPUs, memory, switching devices and high-speed interconnect components.
Cooling must therefore be designed around the entire rack-scale system.
53. Scale-Up Networking and Liquid Cooling
Liquid cooling is increasingly relevant to high-density AI systems because air cooling can become difficult at very high rack power densities.
Cooling requirements cover not only GPUs but also high-speed networking components and optical devices where applicable.
The exact cooling architecture depends on the system design.
54. Scale-Up Networking and Optical Interconnects
Electrical interconnects are highly effective over very short distances, but signal loss and power consumption become increasingly challenging as distance and data rate increase.
Optical technology can extend high-bandwidth communication beyond the practical limits of purely electrical connections.
This makes optical interconnects relevant to future rack-scale and system-scale AI architectures.
55. Optical Engine in AI Scale-Up Networks
An optical engine is an optoelectronic subsystem that performs optical transmission and reception.
It can integrate components such as lasers, modulators, photodetectors, drivers and TIAs.
In advanced AI systems, optical engines can be positioned close to switching or accelerator silicon to reduce high-speed electrical path length.
56. Optical Transceiver vs Optical Engine
| Category | Optical Engine | Optical Transceiver |
|---|---|---|
| Primary Role | Core optoelectronic subsystem | Complete optical interface |
| Typical Position | Inside or close to the system | Often front-panel |
| Host Interface | System dependent | Defined by module architecture |
| Integration | High potential | Modular |
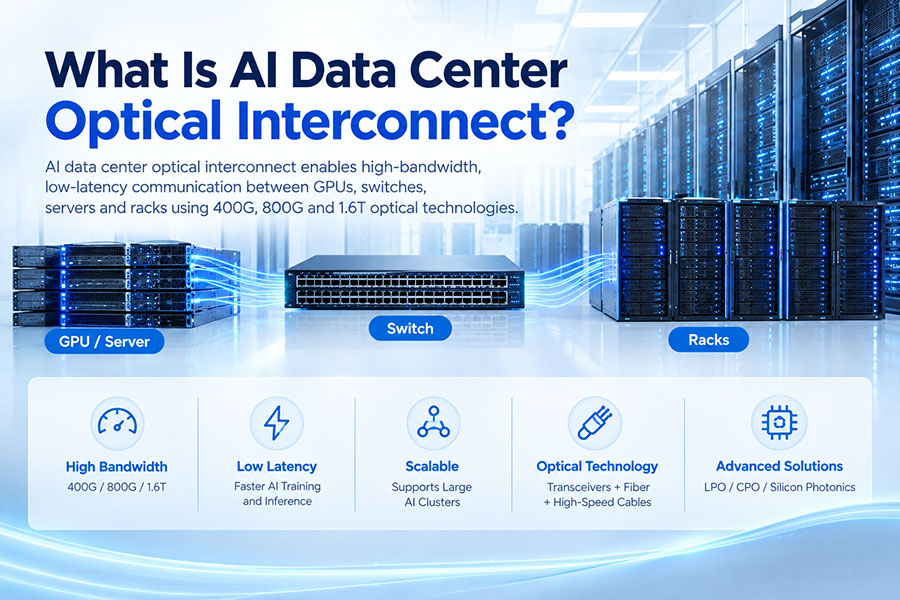
| AI Use | CPO, NPO and integrated optical systems | Scale-out and other optical network connections |
57. Scale-Up Networking and CPO
Co-Packaged Optics places optical engines close to the switching or computing silicon.
This can reduce the electrical path between high-speed SerDes and optical conversion.
CPO is therefore one possible architecture for addressing the electrical and thermal challenges of future high-bandwidth AI systems.
58. Scale-Up Networking and NPO
Near-Packaged Optics places optical engines close to the ASIC without requiring exactly the same package-level integration as CPO.
This approach can reduce electrical distance while retaining more separation between the optical subsystem and the main silicon package.
59. Scale-Up Networking and Coherent Optics
Coherent optical technology is generally associated with longer optical transmission distances and high-capacity telecom or data center interconnect applications.
It is not normally the first architecture considered for very short accelerator-to-accelerator connections, where simpler high-speed interconnects may be more appropriate.
However, optical technology for future AI systems can span multiple distance and architectural categories.
60. Scale-Up Networking and Silicon Photonics
Silicon photonics provides an integration platform for optical components including waveguides, modulators, couplers and multiplexers.
It can support compact optical engines designed for high-density AI and data center systems.
Silicon photonics can therefore become part of the physical layer used by future high-bandwidth scale-up architectures.
61. Scale-Up Networking and VCSEL
VCSEL technology is commonly associated with short-reach optical communication.
VCSEL arrays can provide multiple optical channels in compact parallel optical architectures.
For AI systems, VCSEL-based optical interconnects can be considered for selected short-reach applications where multimode fiber and parallel optics are appropriate.
62. Scale-Up Networking and EML
EML combines a semiconductor laser with an electro-absorption modulator.
It is commonly used for high-speed single-mode and WDM optical transmission.
EML can therefore be relevant to AI optical links where single-mode fiber, high-speed modulation and greater transmission distance are required.
63. Scale-Up Networking and DAC
Direct Attach Copper can provide a simple and low-cost solution for very short high-speed connections.
Because electrical loss increases with distance and signaling speed, DAC is generally most suitable where the physical connection is short.
It can therefore complement optical interconnects within AI systems.
64. Scale-Up Networking and AOC
Active Optical Cables integrate optical transceivers into a fixed cable assembly.
AOC can provide optical transmission for short-to-moderate fixed connections without requiring separate pluggable modules at both ends.
The choice between DAC, AOC and pluggable optics depends on distance, bandwidth, density and serviceability requirements.
65. DAC vs AOC vs Optical Transceiver for AI
| Solution | Medium | Typical Role |
|---|---|---|
| DAC | Copper | Very short high-speed connections |
| AOC | Optical fiber | Fixed optical connections |
| Optical Transceiver | Optical fiber | Flexible pluggable connections |
| Optical Engine | Optical/electrical subsystem | Highly integrated optical architectures |
66. Scale-Up Networking and Optical Distance
The appropriate interconnect technology depends strongly on distance.
Very short connections can use high-speed electrical links, while longer connections increasingly benefit from optical transmission.
Future AI architectures may therefore use different interconnect technologies at different physical layers.
67. Scale-Up Networking and Signal Integrity
Signal integrity becomes more difficult as electrical lane rates increase.
Loss, reflections, crosstalk, jitter and inter-symbol interference can reduce the usable communication margin.
Shortening the electrical path or moving the optical conversion point closer to the accelerator can help address these challenges.
68. Scale-Up Networking and DSP
Some optical links use digital signal processors to compensate for electrical or optical impairments.
However, a scale-up fabric does not inherently require a DSP.
The required signal-processing architecture depends on the electrical or optical technology, transmission distance and system implementation.
69. Scale-Up Networking and LPO
Linear Pluggable Optics removes the conventional high-speed DSP from many pluggable optical modules.
This can reduce module power and latency, but it places greater responsibility on the host SerDes and electrical channel.
LPO is therefore a different design approach from scale-up networking itself and can be relevant to optical connectivity used around AI systems.
70. Scale-Up Networking and Switch Bandwidth
As the number of accelerators in a scale-up domain increases, the switching fabric must provide sufficient aggregate bandwidth.
Insufficient switching capacity can create contention even when individual GPU links provide very high bandwidth.
Switch radix, port bandwidth and topology therefore become important scaling parameters.
71. Scale-Up Network Radix
Radix describes the number of ports available on a switching device.
Higher radix can allow more accelerators to connect to a single switching stage and can simplify some large-scale topologies.
The practical benefit depends on the complete network design.
72. Scale-Up Network Oversubscription
Oversubscription occurs when the aggregate capacity of connected devices exceeds the available capacity of upstream paths.
Communication-intensive AI workloads can be sensitive to oversubscription because many accelerators may transmit simultaneously.
Scale-up fabrics therefore aim to provide sufficient internal bandwidth for demanding collective communication patterns.
73. Scale-Up Networking and Blocking
Blocking occurs when multiple communication flows compete for limited network capacity.
A blocked scale-up fabric can increase collective operation time and cause accelerators to wait.
Topology design and switching capacity are important factors in reducing unnecessary blocking.
74. Scale-Up Networking and Reliability
A large accelerator domain contains many links and switching components.
Failures can affect communication between portions of the system and potentially interrupt large workloads.
Advanced systems can use redundancy, telemetry, fault detection and rerouting mechanisms to improve availability.
75. Scale-Up Network Monitoring
Monitoring provides visibility into link health, bandwidth utilization, errors, latency and other operating conditions.
At large scale, detailed telemetry can help identify failing links or communication bottlenecks before they significantly affect workload performance.
76. Scale-Up Networking and Software Stack
The software stack includes drivers, communication libraries, workload frameworks and system management tools.
These components determine how applications use the available scale-up fabric.
Efficient software can select suitable communication algorithms and paths according to the physical topology.
77. Scale-Up Networking and AI Frameworks
AI frameworks distribute workloads across multiple accelerators and invoke communication operations as part of training or inference.
The framework, communication library and hardware interconnect therefore need to work together.
Communication-aware scheduling can help improve overall system efficiency.
78. Scale-Up Networking and System Co-Design
High-performance AI systems increasingly require co-design across GPUs, memory, networking, cooling, software and power infrastructure.
Optimizing the interconnect independently of the accelerator and software can leave performance on the table.
Scale-up networking is therefore best understood as one part of a complete accelerator platform.
79. Future AI Scale-Up Networking
AI workloads continue to increase in model size, accelerator count and communication intensity.
Future scale-up architectures are expected to focus on higher bandwidth, lower latency, larger accelerator domains, better topology efficiency and improved energy efficiency.
Optical interconnects, optical engines, silicon photonics and other advanced technologies may become increasingly important as electrical interconnects approach their practical limits.
80. AI Scale-Up Networking: Final Comparison
| Category | AI Scale-Up Networking |
|---|---|
| Main Purpose | Connect tightly coupled GPUs and accelerators |
| Primary Traffic | GPU-to-GPU communication |
| Key Requirements | High bandwidth, low latency and predictable communication |
| Common Technologies | NVLink and other accelerator-specific interconnects |
| Communication Patterns | All-reduce, all-gather, reduce-scatter and all-to-all |
| AI Applications | Distributed training and large-scale inference |
| Complementary Network | Scale-out Ethernet/RoCE or InfiniBand |
| Future Optical Role | Optical engines, silicon photonics and other high-density optical interconnects |
AI scale-up networking is the high-performance communication layer that connects GPUs and accelerators inside a tightly coupled computing domain. Its purpose is to provide the bandwidth and latency characteristics needed for multiple accelerators to cooperate efficiently on demanding AI workloads.
Scale-up and scale-out networking serve different purposes. Scale-up focuses on accelerator-to-accelerator communication within a closely integrated domain, while scale-out connects independent servers across a larger AI cluster.
Technologies such as NVLink demonstrate how dedicated scale-up fabrics can provide high-bandwidth GPU communication. As accelerator performance and system density continue to increase, the physical interconnect itself becomes increasingly important, driving development in advanced electrical links, optical engines, silicon photonics and integrated optical architectures.
For AI data centers, scale-up networking should therefore be evaluated together with GPU architecture, memory bandwidth, communication software, cooling, power consumption and the scale-out fabric. The overall objective is to keep accelerators efficiently communicating and performing useful computation as the size of the AI system increases.
 >

 >
 >
 >
 >
 >
 >
 >