TEL:+86 132 6656 7067


Scale-across networking is an AI networking architecture designed to connect geographically separated data centers so that their computing resources can participate in larger distributed AI workloads.
Scale-up networking connects accelerators within a tightly coupled computing domain, while scale-out networking connects servers and racks within a data center. Scale-across extends the networking model beyond a single data center and links multiple AI infrastructure sites into a larger distributed fabric.
The concept has become increasingly important as AI clusters grow beyond the power, space, cooling and infrastructure limits of a single facility. Instead of treating each data center as an isolated GPU island, scale-across networking aims to connect multiple sites with predictable performance for large-scale AI training and inference.
Scale-across is a relatively new AI networking term rather than a traditional universal networking standard. It is currently used prominently by NVIDIA to describe multi-data-center AI connectivity and technologies such as Spectrum-XGS Ethernet.
1. What Is Scale-Across Networking?
Scale-across networking connects multiple geographically distributed AI data centers through a high-performance network fabric.
The goal is to allow computing resources located at different sites to participate in a coordinated AI workload rather than operating as completely independent clusters.
The distance between sites can range from nearby buildings and campuses to much larger regional or inter-city deployments.
2. Why Is Scale-Across Networking Needed?
Large AI systems require enormous amounts of electrical power, cooling capacity, floor space and physical infrastructure.
A single data center cannot always provide unlimited expansion capacity. When one facility reaches its practical limits, additional AI computing resources may need to be deployed at another location.
Scale-across networking is intended to make these separate sites usable as a larger coordinated AI infrastructure.
3. Scale-Up, Scale-Out and Scale-Across
| Networking Layer | Main Scope | Primary Purpose |
|---|---|---|
| Scale-Up | Within a tightly coupled accelerator domain | GPU-to-GPU communication |
| Scale-Out | Across servers and racks | Connect compute nodes within a data center |
| Scale-Across | Across geographically separated sites | Connect multiple AI data centers |
4. Scale-Up Networking
Scale-up networking connects GPUs and accelerators within a tightly integrated computing domain.
Technologies such as NVLink are examples of scale-up interconnects designed for high-bandwidth, low-latency accelerator communication.
The physical distance is typically short compared with inter-data-center networking.
5. Scale-Out Networking
Scale-out networking connects servers and racks within an AI data center.
Ethernet with RDMA technologies such as RoCE and dedicated high-performance fabrics such as InfiniBand can be used to connect large numbers of compute nodes.
Scale-out provides the cluster-level network required after individual accelerator systems have been connected through scale-up fabrics.
6. Scale-Across Networking
Scale-across adds another networking dimension by extending AI connectivity between separate data centers.
The objective is not simply to provide conventional WAN connectivity, but to create a network environment suitable for communication-intensive AI workloads across longer distances.
This introduces challenges that are less significant inside a single facility, particularly propagation delay, congestion and performance variability.
7. Scale-Across vs Traditional WAN
| Feature | Traditional WAN | Scale-Across AI Networking |
|---|---|---|
| Main Purpose | Connect locations and users | Connect distributed AI computing resources |
| Traffic | General application traffic | High-volume AI communication |
| Latency Requirement | Application dependent | Very important |
| Congestion Control | General network optimization | AI workload aware |
| Performance Target | General connectivity | Predictable throughput and latency |
| Typical Architecture | Routers and WAN links | AI-optimized switches, NICs and inter-data-center links |
8. Inter-Data-Center AI Networking
Scale-across networking can be understood as an AI-optimized form of inter-data-center networking.
Instead of treating the connection between two sites as a conventional application network, the fabric is designed to support communication patterns generated by distributed AI workloads.
9. What Is an AI Factory?
An AI factory is a large computing infrastructure designed to generate AI models, inference services or other AI workloads at scale.
An AI factory can contain large numbers of GPUs, networking equipment, storage systems, power infrastructure and cooling systems.
Scale-across networking can connect multiple AI factories so that their computing resources can participate in broader distributed workloads.
10. Distributed AI Data Centers
Distributed AI data centers can be deployed at multiple physical sites rather than inside one building.
This can help organizations expand computing capacity when a single location has insufficient power or physical capacity.
The network then becomes the mechanism for coordinating those distributed resources.
11. Why Distance Matters in Scale-Across Networking
Distance introduces physical propagation delay.
Optical signals travel through fiber at a finite speed, so a longer fiber path creates additional latency even when the networking equipment itself introduces very little processing delay.
For highly synchronized AI workloads, this additional latency can become an important performance factor.
12. Fiber Propagation Delay
Optical signals in fiber travel at roughly two-thirds the speed of light in vacuum.
A commonly used engineering approximation is about 5 nanoseconds of propagation delay per meter of optical fiber.
As the distance increases from kilometers to tens or hundreds of kilometers, the accumulated propagation delay becomes substantial.
13. Why AI Is Sensitive to Long-Distance Latency
Many AI workloads operate in coordinated and synchronized stages.
When multiple computing nodes participate in the same operation, slower communication can cause some resources to wait for data from other locations.
This makes network latency and latency variability important considerations for distributed AI workloads.
14. Latency vs Bandwidth in Scale-Across Networks
| Metric | Meaning | Importance |
|---|---|---|
| Latency | Time required for information to travel | Important for synchronization |
| Bandwidth | Amount of data transported per unit of time | Important for large transfers |
| Jitter | Variation in delivery timing | Important for predictable workload performance |
| Throughput | Actual useful data delivery rate | Determines application efficiency |
15. Why Jitter Matters
Jitter is the variation in communication timing.
Two networks can have similar average latency but significantly different latency variation.
For synchronized AI workloads, unpredictable delays can make workload execution less stable because different parts of the distributed system may complete communication at different times.
16. Scale-Across and Congestion
Congestion occurs when demand for a network path exceeds its available capacity.
AI workloads can generate synchronized bursts in which many nodes transmit at the same time.
When those bursts cross a long-distance network, congestion can have a significant effect on application performance.
17. Why Conventional Deep Buffers Are Not Always Enough
Large buffers can absorb temporary traffic bursts, but they also introduce additional queuing delay when traffic accumulates.
For AI workloads, excessive buffering can increase latency and latency variation.
Scale-across architectures therefore require more than simply increasing switch buffer capacity.
18. Distance-Aware Networking
Distance-aware networking takes physical path distance into account when making networking decisions.
Routing, congestion control and other algorithms can be adjusted according to the characteristics of the path between communicating nodes.
This approach is particularly relevant when one AI fabric spans sites with significantly different physical distances.
19. Distance-Aware Congestion Control
Distance-aware congestion control can account for the fact that long-distance paths have greater propagation delay than short paths.
The control algorithm can therefore be designed to react appropriately to the characteristics of the path rather than assuming that every network connection behaves the same way.
20. Adaptive Routing in Scale-Across Networks
Adaptive routing allows traffic to use different paths according to current network conditions.
When one path becomes congested, traffic can potentially be redirected toward another available path.
This can help distribute load across a multi-site fabric.
21. Performance Isolation
Performance isolation means preventing one traffic flow or workload from significantly degrading the performance of another.
This becomes important in large AI fabrics where multiple distributed jobs may share the same infrastructure.
Traffic scheduling and congestion-control mechanisms can be used to improve isolation.
22. Scale-Across and AI Training
Distributed AI training can divide computation across GPUs located in different data centers.
The participating sites need to exchange model information during the training process.
If the communication fabric is not sufficiently efficient, the additional distance between locations can reduce the benefits of distributing the workload.
23. Scale-Across and AI Inference
Distributed inference can also span multiple physical sites.
Large inference systems may distribute model components, data or workloads among different AI facilities.
In these cases, predictable network performance can help maintain stable service behavior.
24. Scale-Across and Collective Communication
AI workloads frequently use collective operations such as all-reduce, all-gather and reduce-scatter.
These operations involve communication among multiple computing nodes.
When the nodes are distributed across different data centers, the additional propagation delay and congestion characteristics of the inter-site network become part of the collective operation.
25. Scale-Across and All-Reduce
All-reduce combines information from multiple computing nodes and distributes the result back to participating nodes.
In a geographically distributed AI system, some of those communication paths may cross data center boundaries.
High inter-site latency or congestion can therefore affect the completion time of the collective operation.
26. Scale-Across and NCCL
NCCL is a GPU communication library widely used for collective communication.
AI network architectures that span multiple sites need communication software and networking infrastructure capable of handling the physical characteristics of those longer paths.
Network topology and software behavior therefore become closely connected in large distributed AI systems.
27. Scale-Across and GPU Utilization
GPU utilization can decrease when accelerators spend significant time waiting for communication.
In a geographically distributed training environment, communication delay can become more important because of the physical distance between sites.
An efficient scale-across fabric attempts to minimize unnecessary waiting and maintain predictable data delivery.
28. Scale-Across and Training Efficiency
Training efficiency depends on the ratio between useful computation and communication overhead.
As the physical distance between participating sites increases, communication overhead can become a larger part of total execution time.
Network optimization is therefore important when distributing a single workload across multiple locations.
29. Scale-Across and Data Center Location
The physical location of AI data centers can influence network latency, available power, cooling capacity and optical infrastructure.
Distributed deployment may allow computing capacity to be placed where infrastructure resources are available.
The network must then connect those locations efficiently enough to support the intended workloads.
30. Campus-Scale AI Networking
A campus-scale AI network can connect multiple buildings within a relatively limited geographic area.
Although the distance may be shorter than an inter-city connection, the network can still experience different propagation delays and physical routing conditions compared with an internal data center fabric.
Scale-across concepts can therefore apply even when connected facilities are relatively close together.
31. Regional AI Networking
Regional scale-across networks can connect AI facilities located across the same metropolitan or regional area.
This can create a larger computing pool while allowing different sites to contribute computing or infrastructure resources.
32. Inter-City AI Networking
Inter-city AI networking introduces significantly greater propagation delay than campus connectivity.
Distributed AI workloads operating over these distances therefore require careful control of latency, congestion and communication patterns.
Optical transport becomes particularly important as the physical distance increases.
33. Inter-Data-Center Optical Connectivity
Optical fiber is the primary physical medium for high-bandwidth communication between data centers.
Fiber supports high aggregate bandwidth over distances that are impractical for direct copper connections.
Depending on distance, the optical system can use different transceiver, coherent or optical transport architectures.
34. Optical Transceivers in Scale-Across Networks
Optical transceivers convert high-speed electrical signals into optical signals for transmission through fiber and perform the reverse conversion at the receiving site.
For scale-across networking, the required transceiver architecture depends on physical distance, bandwidth, optical budget and network topology.
35. 400G Optical Connectivity
400G optical interfaces can provide high-bandwidth connections between AI network systems.
Different 400G architectures support different distances and fiber types, ranging from short-reach parallel optics to longer single-mode WDM solutions.
The appropriate architecture depends on the scale-across link requirements.
36. 800G Optical Connectivity
800G optical transceivers provide greater bandwidth per interface and can reduce the number of physical links required for a given aggregate capacity.
They can therefore contribute to higher-density inter-data-center AI connectivity when supported by the network equipment and optical infrastructure.
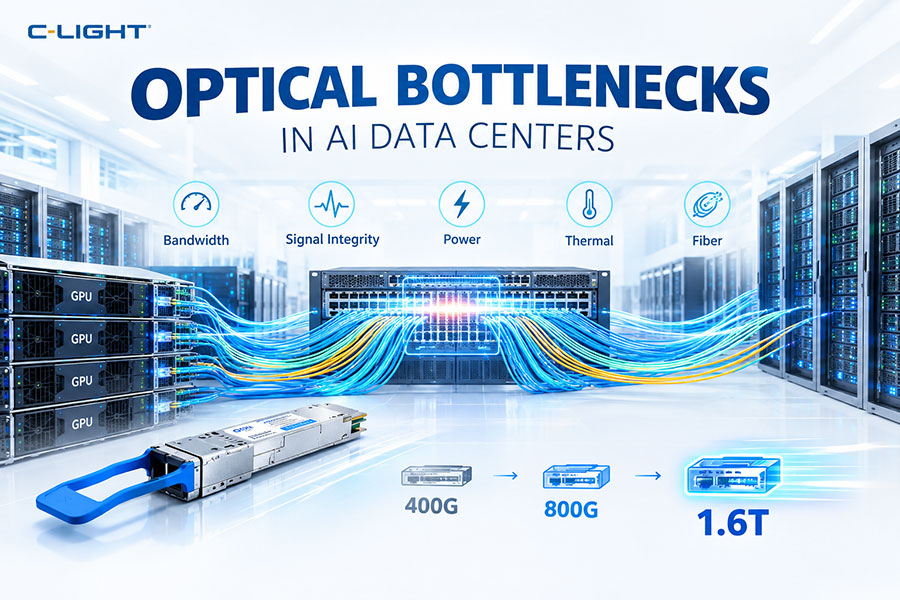
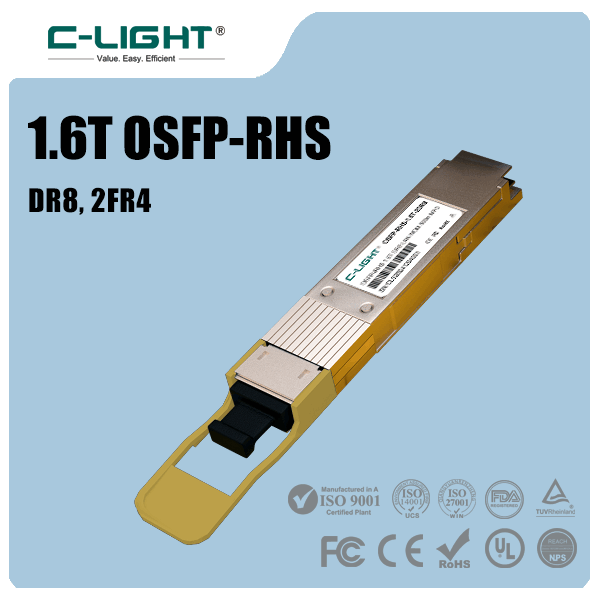
37. 1.6T Optical Connectivity
1.6T optical interfaces are being developed for next-generation data center and AI networking.
Higher interface speeds can increase bandwidth density but also create additional requirements for electrical signal integrity, optical engines, thermal management and system power.
38. WDM in Scale-Across Networks
Wavelength-division multiplexing allows multiple optical channels at different wavelengths to share the same fiber.
WDM can increase bandwidth density and reduce the number of physical fiber pairs needed for high-capacity links.
This makes WDM an important technology for many high-speed single-mode optical connections.
39. Coherent Optics in Scale-Across Networks
Coherent optics is widely used for higher-capacity and longer-distance optical transmission.
Coherent systems use advanced modulation, optical detection and DSP to recover both amplitude and phase information.
For longer scale-across links, coherent technology can provide the reach and spectral efficiency required by the optical transport system.
40. Direct-Detection Optics in Scale-Across Networks
Direct-detection optical technologies can also be used for suitable shorter-distance applications.
The choice between direct detection and coherent transmission depends on distance, optical budget, bandwidth, modulation, power and system architecture.
41. Optical Engine in Scale-Across Networking
An optical engine provides the core optoelectronic transmit and receive functions in an optical system.
It can contain lasers, modulators, photodetectors, drivers, TIAs and optical coupling components.
Advanced optical engines can be used in high-density AI networking equipment and integrated optical systems.
42. Scale-Across and Optical Engines
Optical engines are more commonly discussed in relation to highly integrated switch or system architectures such as NPO and CPO.
For scale-across networking, optical engines can form part of the switching or optical transport equipment used to connect distributed AI sites.
The specific engine architecture depends on the transmission technology.
43. Scale-Across and CPO
Co-Packaged Optics places optical engines close to switching ASICs.
CPO and scale-across describe different aspects of network architecture.
CPO focuses on the physical integration of optics and switching silicon, while scale-across focuses on extending AI networking between geographically separated sites.
44. Scale-Across and NPO
Near-Packaged Optics places optical engines close to the switch ASIC while keeping the optical subsystem physically separate from the ASIC package.
NPO can support high-bandwidth switching systems that participate in scale-across fabrics.
The two concepts are complementary rather than mutually exclusive.
45. Scale-Across and LPO
Linear Pluggable Optics removes the conventional high-speed DSP from many optical modules.
LPO is a signal-processing architecture, while scale-across is a network-scope architecture.
They therefore address different problems and can coexist within a broader AI networking system where the physical link architecture permits.
46. Scale-Across and DSP
DSP can compensate for electrical or optical signal impairments, but processing does not eliminate physical propagation delay.
For long-distance AI links, both signal processing and network-level latency must be considered.
Scale-across networking can therefore require specialized algorithms in addition to high-performance optical hardware.
47. Scale-Across and Ethernet
Ethernet can provide the underlying network framework for scale-across architectures.
AI-optimized Ethernet approaches can combine high-speed switches, network adapters, congestion control and software support to extend AI networking beyond a single data center.
NVIDIA's Spectrum-XGS Ethernet is one example of a platform explicitly positioned for scale-across networking.
48. What Is Spectrum-XGS Ethernet?
Spectrum-XGS Ethernet is an NVIDIA technology positioned as a scale-across networking solution for connecting distributed AI data centers.
NVIDIA describes it as an extension of the Spectrum-X Ethernet platform designed to connect AI factories across longer distances.
It uses the broader Spectrum-X ecosystem while adding mechanisms intended for the unique characteristics of multi-data-center AI networking.
49. How Does Spectrum-XGS Support Scale-Across?
Spectrum-XGS is designed around the idea that network behavior should account for physical distance.
NVIDIA describes distance-aware congestion control and adaptive routing mechanisms intended to maintain AI application performance across distributed data centers.
This approach is different from treating inter-data-center connectivity as a conventional best-effort WAN connection.
50. Scale-Across and Existing Network Infrastructure
A practical scale-across deployment needs to integrate switching, network adapters, optical transport, routing, monitoring and workload software.
The network must also account for the characteristics of the physical fiber path and the distance between participating sites.
Existing infrastructure can therefore require additional optimization before it can support highly synchronized distributed AI workloads efficiently.
51. Scale-Across and Network Resilience
Connecting multiple data centers creates additional potential failure points.
Fiber cuts, equipment failures, power events and network congestion can affect communication between sites.
Redundant paths, monitoring and traffic rerouting are therefore important parts of a resilient scale-across architecture.
52. Scale-Across and Fault Recovery
Fault recovery can be more complicated when a workload spans geographically separated facilities.
The network must detect failures and redirect traffic without creating excessive disruption.
Recovery mechanisms should be designed together with the distributed AI software and workload scheduler.
53. Scale-Across and Network Telemetry
Telemetry provides visibility into network utilization, latency, packet behavior, congestion and link health.
For geographically distributed AI fabrics, telemetry can help operators identify whether performance problems originate from a specific site, optical path or network segment.
54. Scale-Across and Congestion Monitoring
Congestion monitoring is particularly important because long-distance traffic has a different latency profile from local data center traffic.
Network operators can use traffic statistics and telemetry to identify congested links and adjust traffic distribution or routing policies.
55. Scale-Across and Network Topology
A scale-across fabric can connect multiple data centers in different geographic arrangements.
The topology may include redundant inter-site paths, regional aggregation points or direct site-to-site connections.
The optimal design depends on site location, bandwidth requirements, workload communication patterns and resilience requirements.
56. Scale-Across Network Topology Example
A simplified architecture can be represented as:
AI Data Center A → AI Switch Fabric → Optical Transport → AI Data Center B.
A larger deployment can extend this model:
AI Data Center A ↔ AI Data Center B ↔ AI Data Center C ↔ AI Data Center D.
Redundant optical paths can be added to provide alternative routes between sites.
57. Scale-Across and Multi-Site AI Factories
Multiple AI factories can contribute computing capacity to one larger logical infrastructure.
This can allow organizations to use capacity that would otherwise remain separated by geographic boundaries.
The network must provide sufficiently predictable performance for the workloads that cross those boundaries.
58. Scale-Across and Resource Pooling
Resource pooling means treating distributed computing capacity as a larger shared resource.
When the network can provide suitable performance, workloads can potentially be scheduled across multiple sites according to available compute and infrastructure resources.
This can improve utilization of distributed capacity.
59. Scale-Across and Power Constraints
Power availability is one reason AI infrastructure may need to expand beyond a single facility.
A data center may reach a practical power limit before the organization reaches its desired computing capacity.
Distributing AI infrastructure across multiple locations can provide additional power availability, while scale-across networking connects those resources.
60. Scale-Across and Cooling Constraints
AI accelerators and high-speed networking equipment create substantial heat loads.
Cooling capacity can therefore become a limiting factor in dense AI facilities.
Distributing compute resources across multiple sites can help spread thermal infrastructure requirements.
61. Scale-Across and Data Center Space
Physical space is another major constraint for very large AI clusters.
GPU servers, switches, optical equipment, power distribution and cooling systems all require physical space.
Multi-site deployment can provide additional room for expansion.
62. Scale-Across and AI Cluster Expansion
Traditional cluster expansion adds more servers within an existing data center.
Scale-across adds another dimension by allowing additional AI capacity to be connected at another geographic location.
This can extend cluster growth beyond the physical limits of a single site.
63. Scale-Across and Network Capacity Planning
Capacity planning must consider both compute growth and network growth.
Adding more GPUs across multiple sites increases not only the amount of computing power but also the amount of inter-site communication that may be generated.
The optical and network fabric must therefore scale alongside the compute infrastructure.
64. Scale-Across and Optical Bandwidth Density
Higher-speed optical transceivers can increase the amount of traffic carried by each physical network interface.
400G, 800G and emerging 1.6T technologies can reduce the number of individual links needed for high aggregate bandwidth.
This can simplify some aspects of large-scale optical network design.
65. Scale-Across and Front-Panel Density
High-capacity optical modules can increase switch bandwidth without requiring a proportional increase in front-panel port count.
This is especially important when switch systems must connect large numbers of high-speed links.
Higher-density optical interfaces can therefore complement scale-across networking.
66. Scale-Across and Power Efficiency
Inter-site network equipment consumes power through switches, network adapters, optical transceivers, optical transport equipment and cooling systems.
Improving bandwidth per watt can reduce the infrastructure power required to connect distributed AI resources.
Power efficiency therefore remains an important consideration even when the primary objective is network scale.
67. Scale-Across and Thermal Management
High-speed networking systems generate heat, especially when large numbers of optical ports are deployed.
Switches and optical transport equipment need appropriate air or liquid cooling depending on system density.
Thermal planning becomes more complex as the scale-across network grows.
68. Scale-Across and Liquid Cooling
Liquid cooling is increasingly used in high-density AI infrastructure.
The need for liquid cooling is primarily determined by component power density rather than by the concept of scale-across itself.
High-density switches and optical systems may therefore require advanced thermal solutions as bandwidth increases.
69. Scale-Across vs Scale-Out Architecture
| Category | Scale-Out | Scale-Across |
|---|---|---|
| Geographic Scope | Usually within one data center | Multiple geographically separated data centers |
| Primary Endpoint | Servers and AI nodes | AI factories or data center fabrics |
| Distance | Short to local data center distances | Campus to inter-city or longer distances |
| Primary Challenge | Fabric scale and congestion | Distance, latency, congestion and scale |
| Typical Technology | Ethernet/RoCE or InfiniBand | AI-optimized inter-data-center networking |
70. Scale-Across vs Scale-Up Architecture
| Category | Scale-Up | Scale-Across |
|---|---|---|
| Endpoint | GPU or accelerator | Data center or AI factory |
| Physical Distance | Very short to rack-scale | Multiple sites |
| Main Goal | Accelerator communication | Multi-site AI resource integration |
| Typical Interconnect | Dedicated accelerator fabric | High-performance optical network fabric |
| Latency Source | Switch and link latency | Equipment plus physical propagation delay |
71. Scale-Across and AI Factory Networking Layers
A large AI infrastructure can be viewed as several networking layers:
Scale-up connects accelerators, scale-out connects servers and racks, and scale-across connects separate AI data centers.
These layers can operate together rather than replacing one another.
72. A Complete AI Networking Architecture
A simplified architecture can be represented as:
GPU → Scale-Up Fabric → AI Server → Scale-Out Fabric → Data Center Network → Scale-Across Fabric → Remote AI Data Center.
Each layer solves a different connectivity problem and has different requirements for bandwidth, latency, topology and physical infrastructure.
73. Scale-Across and Software-Defined Networking
Large distributed AI fabrics require software to manage routes, congestion, traffic priorities and system health.
Software-defined networking techniques can provide centralized or distributed control over the behavior of a large multi-site network.
The exact implementation depends on the networking platform.
74. Scale-Across and Workload Scheduling
Workload scheduling determines where AI jobs are executed.
When compute resources are distributed across multiple data centers, network characteristics can become part of scheduling decisions.
Some workloads may be more suitable for local execution, while others can tolerate or benefit from distributed resource placement.
75. Scale-Across and Distributed Inference
Distributed inference can place different stages of model execution at different locations.
This architecture requires careful coordination between compute resources and the network connecting them.
Latency becomes particularly important for applications with strict response-time requirements.
76. Scale-Across and Multi-Data-Center Training
Multi-data-center training allows a single AI training workload to use resources distributed across several locations.
The network must provide sufficient throughput and predictable latency so that communication does not dominate the workload.
This is one of the most demanding use cases for scale-across networking.
77. Scale-Across and AI Grid Architectures
A broader AI grid can connect distributed AI infrastructure across multiple locations and network domains.
Such an architecture can include centralized AI factories, regional computing sites and other AI infrastructure nodes.
Scale-across networking can provide the high-performance connectivity layer between those sites.
78. Scale-Across Networking Challenges
The major challenges include physical propagation delay, congestion, network jitter, optical capacity, traffic engineering, fault recovery, power consumption and operational complexity.
These challenges become increasingly difficult as the number of locations and physical distance increase.
79. Future of Scale-Across Networking
As AI clusters expand beyond individual data centers, networking between sites is likely to become an increasingly important architectural consideration.
Future scale-across systems are expected to focus on higher bandwidth, better congestion control, distance-aware networking, stronger telemetry, improved optical efficiency and greater network resilience.
Optical transceivers, coherent optics, silicon photonics, optical engines and high-density switching technologies can all contribute to this evolution.
80. What Is Scale-Across Networking? Final Comparison
| Category | Scale-Across Networking |
|---|---|
| Definition | High-performance networking between geographically separated AI data centers |
| Main Purpose | Combine distributed AI computing resources into a larger fabric |
| Relationship to Scale-Up | Extends beyond accelerator-level connectivity |
| Relationship to Scale-Out | Extends beyond a single data center |
| Key Challenges | Distance, latency, jitter, congestion and resilience |
| Network Technologies | AI-optimized Ethernet and high-performance optical transport |
| Optical Connectivity | 400G, 800G, 1.6T and higher-capacity architectures |
| Optical Technologies | WDM, coherent optics, optical engines and silicon photonics |
| Main Applications | Multi-data-center AI training, inference and distributed AI factories |
Scale-across networking extends AI connectivity beyond the boundaries of a single data center. While scale-up connects accelerators and scale-out connects servers and racks, scale-across connects geographically separated AI facilities into a larger distributed computing environment.
The primary challenge is that physical distance introduces propagation delay and changes the behavior of congestion, routing and collective communication. AI workloads are particularly sensitive to these factors because large numbers of computing resources often communicate in synchronized patterns.
High-speed optical connectivity is a fundamental part of this architecture. 400G, 800G and emerging 1.6T interfaces can provide the bandwidth required by large AI fabrics, while WDM, coherent optics, optical engines and silicon photonics can support different distance and density requirements.
Scale-across should therefore be viewed as a network architecture rather than a single optical module or Ethernet standard. Its success depends on the coordinated design of AI compute, switches, network adapters, optical links, congestion control, routing, telemetry and distributed workload software.
 >

 >
 >
 >
 >
 >
 >
 >