TEL:+86 132 6656 7067


Data center networking has been built on a single assumption for decades: every packet is individually inspected, buffered, and forwarded by electronic switches. This packet-switched model—the foundation of Ethernet and IP—has scaled remarkably well from 10 Mbps to 800 Gbps. But AI training clusters are pushing it to its limits. The network now accounts for 20 to 30 percent of total power consumption in AI clusters, and a single 10,000-GPU cluster can consume over 10 megawatts just for interconnect. Worse, expensive GPUs sit idle up to 60 percent of the time waiting for data to arrive through a network that cannot route it fast enough.
Optical circuit switching (OCS) offers a fundamentally different approach. Instead of inspecting every packet, OCS establishes a dedicated light path between two endpoints—a physical optical circuit that data traverses without any electronic processing in between. The switch does not read packet headers, does not buffer data, and does not convert signals between optical and electrical domains. It simply redirects light from one fiber to another, much like a railroad switch redirects a train onto a different track.
This architectural difference—packet-by-packet routing versus circuit-level light path establishment—produces radically different characteristics in latency, power consumption, protocol transparency, and scalability. Understanding these differences is essential for designing networks that can support the next generation of AI infrastructure.
1. The Fundamental Architectural Divide
Electronic packet switching and optical circuit switching differ not just in technology but in the basic model of how data moves through a network.
1.1 How Electronic Packet Switching Works
In an electronic packet-switched network, data is divided into packets. Each packet carries a header containing address information. When a packet arrives at a switch, the switch performs a series of operations: it converts the incoming optical signal to electrical form, reads the packet header, looks up the destination in a routing table, queues the packet in a buffer if the output port is busy, and eventually forwards it to the next hop. At the next switch, the process repeats. Every hop requires an optical-to-electrical-to-optical conversion, packet processing, and buffering.
This model is flexible and handles arbitrary traffic patterns. Any source can send to any destination at any time, and the network dynamically routes each packet based on current conditions. The trade-off is overhead: each hop adds latency, consumes power for OEO conversion and packet processing, and introduces the possibility of congestion and packet loss.
1.2 How Optical Circuit Switching Works
In an optical circuit-switched network, the switch establishes a dedicated optical path between an input port and an output port before data transmission begins. This path remains in place for the duration of the connection. Data flows through the switch entirely in the optical domain—no OEO conversion, no packet inspection, no buffering. The switch is transparent to the data rate, modulation format, and protocol being carried.
The core limitation of OCS is that it cannot buffer light. Practical optical switches are circuit-based because it is currently infeasible to store photons for any meaningful period of time. This means OCS must establish connections on a schedule rather than on a per-packet basis. The control plane determines when and how to reconfigure the switch, and the data plane simply executes those reconfigurations.
| Dimension | Electronic Packet Switching (EPS) | Optical Circuit Switching (OCS) |
|---|---|---|
| Switching Granularity | Per packet | Per circuit (light path) |
| Data Processing | Header inspection, routing lookup, buffering | None (transparent pass-through) |
| OEO Conversion | At every hop | None within the switch |
| Buffering | Electronic buffers at each port | No optical buffering possible |
| Protocol Awareness | Protocol-dependent | Protocol-transparent, rate-agnostic |
| Control Plane | Distributed, local decisions per packet | Centralized or scheduled |
| Reconfiguration Speed | Per packet (nanoseconds) | Milliseconds to microseconds |
2. The Packet-Switching Bottleneck in AI Clusters
AI training workloads expose weaknesses in packet-switched networks that were tolerable for general-purpose cloud traffic but become critical at scale.
2.1 OEO Conversion Overhead
Every electronic switch in the path requires optical-to-electrical-to-optical conversion. The incoming optical signal is converted to electrical form for packet processing, then converted back to optical for transmission to the next hop. At 400G and 800G port speeds, these conversions consume substantial power. Networking equipment—switches and the DSPs inside optical modules—accounts for 20 to 30 percent of total power consumption in AI clusters. In a 10,000-GPU cluster, interconnect alone can exceed 10 megawatts.
2.2 Tail Latency and Synchronization
AI training relies on collective communication operations—All-Reduce, All-to-All, All-Gather—that synchronize thousands of GPUs. These operations are sensitive to tail latency: the slowest flow in a collective determines the completion time for the entire operation. Packet-switched networks introduce variable latency through buffering, congestion, and per-hop processing. Even a small number of delayed packets can stall the entire collective, forcing thousands of expensive GPUs to wait.
2.3 Hash Collisions and Load Imbalance
Traditional load balancing in packet-switched networks uses ECMP (Equal-Cost Multi-Path) routing, which distributes traffic based on flow-level hashing. AI training generates a small number of very large flows (elephant flows) rather than many small flows. When multiple elephant flows hash to the same link, that link becomes congested while parallel links sit idle. The resulting load imbalance degrades collective performance and wastes bandwidth.
3. How Optical Circuit Switching Eliminates the Bottleneck
OCS addresses each of these bottlenecks by fundamentally changing how data traverses the network.
3.1 Eliminating OEO Conversion
Because OCS keeps data entirely in the optical domain, there is no OEO conversion within the switch. The switch redirects light from input fibers to output fibers using micro-mirrors or other optical steering mechanisms. This eliminates the power consumption of high-speed transceivers, DSPs, and packet-processing ASICs. An OCS-based spine layer can reduce power consumption by nearly 99 percent compared to electrical packet switching, and 8-year lifecycle costs by 76 percent.
3.2 Deterministic, Ultra-Low Latency
OCS provides deterministic latency. Data traverses the switch at the speed of light in fiber, with no buffering, no queuing, and no variable processing delay. The latency through an OCS is measured in nanoseconds—less than 30 nanoseconds for MEMS-based switches and 25 to 75 nanoseconds for piezoelectric designs. This determinism is critical for AI collective operations, where tail latency directly impacts GPU utilization.
3.3 Protocol and Rate Transparency
Because OCS does not inspect or process packets, it is agnostic to data rate and protocol. The same switch can carry Ethernet, InfiniBand, or NVLink traffic, and can support transitions from 400G to 800G to 1.6T without replacing the switching fabric. This future-proofs the network infrastructure and simplifies upgrades: moving from 800G to 1.6T requires only swapping optical modules, not rebuilding the switch layer.
3.4 Flattening the Network Hierarchy
OCS enables network architectures that eliminate entire layers of switching. Google's Apollo OCS deployment, part of its Jupiter data center network, replaced traditional multi-tier CLOS topologies with a flattened Direct Mesh architecture. By creating direct optical paths between endpoints, OCS eliminates the need for spine switch tiers, reducing both capital expenditure and operational complexity.
4. Optical Packet Switching: The Unfinished Alternative
Optical circuit switching is not the only form of optical switching. Optical packet switching (OPS) and optical burst switching (OBS) have been researched for decades as ways to combine the flexibility of packet switching with the efficiency of optical transport.
OPS would route individual packets through the optical domain without OEO conversion, providing packet-level granularity with optical efficiency. OBS would aggregate packets into bursts, switching at the burst level rather than the packet or circuit level. Both approaches face a fundamental obstacle: the lack of practical optical random-access memory. Without the ability to buffer light, OPS and OBS cannot resolve contention—when two packets arrive simultaneously destined for the same output port, one must be delayed or dropped. Fiber delay lines can provide limited buffering, but they are bulky, lossy, and impractical for the microseconds of buffering required in data center networks.
As a result, OPS and OBS remain research topics. All practical optical switches deployed in data centers today are circuit-based. The choice, for now, is between electronic packet switching and optical circuit switching.
5. Deployment Case Study: Google's Apollo OCS
The strongest evidence for OCS viability comes from Google's hyperscale deployment. Google's Mission Apollo initiative replaced traditional electronic switches with thousands of in-house OCS systems, which now form the core of its Jupiter network.
5.1 The Palomar System
Google's OCS systems, known as Palomar, use MEMS-based mirrors to dynamically redirect beams of light. Each Palomar switch creates direct, transparent optical paths between different parts of the network, allowing a vast number of possible connection combinations in a compact and energy-efficient form factor. Wavelength division multiplexing (WDM) increases bandwidth by allowing multiple data streams to share a single fiber.
5.2 Measured Results
The deployment delivered measurable improvements. Compared with Google's previous electronic switching solution, the OCS-based network consumed 40 percent less power and reduced downtime to one-fiftieth of the previous level. The shift to a direct-connect topology simplified the network hierarchy, eliminating an entire spine layer of switches.
5.3 Next-Generation TPU Integration
Google's next-generation TPU, Ironwood, integrates a 3D Torus network topology with the Apollo OCS all-optical network. In this architecture, TPUs within a rack use high-speed copper for short-reach connections, while the all-optical network handles inter-rack data transmission. A single OCS switch consumes only around 100 watts, compared with approximately 3,000 watts for a traditional switch—a 95 percent reduction. Upgrading bandwidth from 800G to 1.6T requires only swapping in higher-speed optical modules rather than rebuilding the entire system.
6. Power Consumption: The Decisive Advantage
Power consumption is the single most compelling argument for OCS in AI data centers. The numbers are stark.
| Metric | Electronic Packet Switching | Optical Circuit Switching |
|---|---|---|
| Per-Switch Power (spine) | ~3,000 W | ~100 W (Google Palomar) |
| Spine-Layer Power Reduction | Baseline | Up to 99% reduction |
| Network-Layer Power Reduction | Baseline | Up to 65% reduction |
| 8-Year Lifecycle Cost Reduction | Baseline | Up to 76% reduction |
| Per-Port Power | Watts to tens of watts | Sub-watt (no SerDes, no DSP) |
A 1 GW data center containing 1 million GPUs would require approximately 10,000 OCS switches. At 100 watts each, the total OCS switching power would be approximately 1 megawatt—compared with the tens of megawatts consumed by an equivalent electronic switching fabric. At the cluster level, replacing electrical packet switching with OCS in the spine layer can yield power savings of 20 to 40 percent across the network infrastructure. More aggressive deployments targeting 100,000-GPU scale report network power reductions exceeding 65 percent.
7. Latency and Determinism
For AI workloads, latency is not just about average delay—it is about determinism. Collective operations require that all participating GPUs complete their communication within a bounded time. Packet-switched networks introduce variable latency through buffering and congestion, creating tail latency that can stall the entire collective.
OCS provides deterministic latency. Once a light path is established, data traverses the switch at a fixed propagation delay determined only by the physical path length. There is no queuing, no congestion, and no variable processing time. The switching latency itself is measured in nanoseconds: Calient's MEMS switches provide less than 30 nanoseconds of latency, Polatis piezoelectric switches provide 25 to 75 nanoseconds, and Telescent robotic switches provide approximately 30 nanoseconds. Reconfiguration time—the time to establish a new light path—is measured in milliseconds for MEMS switches (less than 200 milliseconds) and tens of milliseconds for piezoelectric designs (25 to 50 milliseconds).
For AI training, the reconfiguration time matters less than the transmission latency because training communication patterns are predictable and phase-based. The collective communication phases align well with the slower reconfiguration speed of OCS, allowing the switch to be reconfigured between training iterations rather than within them.
8. Scalability and Port Count
OCS switches scale to port counts that electronic switches cannot match. MEMS-based OCS systems can support 320 ports or more, with some designs reaching over 1,000 ports. Piezoelectric switches support up to 384×384 ports with exceptionally low optical loss. Robotic patch panels can scale to over 10,000 fibers.
The scalability advantage comes from the absence of electronic processing. An electronic switch's port count is limited by the size of its packet-processing ASIC and the power and thermal density of its transceivers. An optical switch's port count is limited by the physical size of its optical steering mechanism and the precision of its alignment. As optical MEMS and silicon photonics technologies mature, port counts continue to increase.
9. The Control Plane Challenge
OCS is not without its challenges. The simplicity of the optical data plane is offset by a more complex control plane. An electronic packet switch makes routing decisions locally, based on information in each packet header. An OCS cannot do this—it has no access to packet headers and cannot make per-packet decisions. Instead, the OCS must be centrally controlled or operate according to a deterministic schedule.
This creates a trade-off. Centralized control introduces the possibility of a single point of failure and adds control-plane latency. Deterministic scheduling works well for predictable traffic patterns like AI training but is inefficient for bursty, unpredictable traffic. Hybrid architectures that combine OCS for large, persistent flows with electronic packet switching for small, dynamic flows are emerging as the practical solution.
10. Hybrid Architectures: The Practical Path Forward
Neither pure optical circuit switching nor pure electronic packet switching is optimal for every workload. The industry consensus is converging on hybrid architectures that use each technology where it performs best.
10.1 OCS for Elephant Flows, EPS for Mice Flows
AI training generates two distinct traffic types. Elephant flows—large, persistent data transfers between GPUs during collective operations—dominate bandwidth. Mice flows—small, bursty control messages and metadata—dominate flow count but consume little bandwidth. OCS excels at routing elephant flows with minimal power and maximum determinism. EPS excels at routing mice flows with per-packet flexibility. A hybrid network assigns each traffic type to the technology that handles it most efficiently.
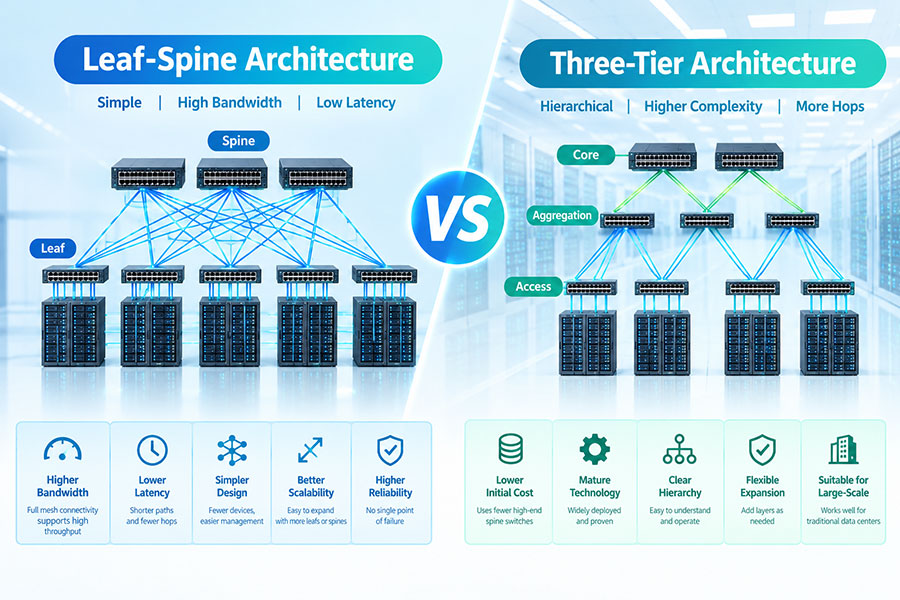
10.2 OCS in the Spine, EPS in the Leaf
In a spine-leaf topology, OCS can replace the spine layer entirely or supplement it. The leaf layer, which connects to servers and handles per-packet processing and congestion management, remains electronic. The spine layer, which carries aggregated traffic between leaf switches, uses OCS to establish direct light paths. This architecture preserves the flexibility of packet switching at the edge while capturing the power and latency benefits of optical switching in the core.
10.3 Dynamic Reconfiguration for Training Phases
AI training alternates between compute phases, where GPUs process data locally, and communication phases, where GPUs exchange gradients and activations. OCS can reconfigure the network topology between phases to match the communication pattern. During All-Reduce, the network forms a ring or tree optimized for gradient reduction. During All-to-All, it forms a mesh optimized for expert routing. This dynamic reconfiguration is not possible with fixed electronic switching.
11. Optical Switch Technologies
Several technologies implement optical circuit switching, each with different characteristics in port count, switching speed, insertion loss, and reliability.
| Technology | Port Count | Switching Speed | Insertion Loss | Key Characteristics |
|---|---|---|---|---|
| 3D MEMS Micromirror | Up to 1,100+ | ~100 ms | ~4 dB | Mature, widely deployed; risk of micromirror stiction |
| Piezoelectric DirectLight | Up to 384 | 25–50 ms | 0.5–2.7 dB | No mechanical wear; high reliability; higher cost |
| Digital Liquid Crystal | Moderate | Milliseconds | Moderate | Low drive voltage, no moving parts; slower than MEMS |
| Robotic Patch Panel | 48–10,000+ | ~90 seconds | <0.3 db=""> | Lowest insertion loss; very slow switching; best for static reconfiguration |
| Silicon Photonic (MZI) | 32 (current) | <0.001 ms=""> | 6.4 dB on-chip | Fastest switching; limited port count due to crosstalk and loss |
MEMS micromirror technology dominates current deployments because it offers the best balance of port count, switching speed, and maturity. Google's Palomar system uses MEMS mirrors. Emerging silicon photonic switches offer dramatically faster switching speeds but are currently limited in port count and suffer from higher insertion loss and crosstalk.
12. Market Trajectory and Adoption
The optical circuit switch market is growing rapidly. The global OCS market was valued at approximately $0.56 billion in 2026 and is projected to reach $2.52 billion by 2032, representing a compound annual growth rate of 28.5 percent. More aggressive forecasts, based on OCS expanding from Google's TPU scale-out networks into NVIDIA and other GPU cluster scale-up networks, project the market exceeding $8 billion by 2030.
Adoption is being driven by hyperscalers seeking to reduce power consumption, improve GPU utilization, and scale beyond the limits of electronic switching. Google has deployed OCS at massive scale. Other hyperscalers and AI infrastructure providers are evaluating or deploying OCS for spine-layer replacement, AI cluster reconfiguration, and scale-across connectivity. The technology is moving from "available" to "deployable, operable, and mass-deployable" as engineering challenges are addressed and operational experience accumulates.
13. Application Mapping: Which Switching for Which Layer
The choice between packet switching and optical circuit switching depends on the network layer and the traffic characteristics at that layer.
| Network Layer | Recommended Switching | Rationale |
|---|---|---|
| Server-to-ToR | Packet switching | Per-packet flexibility required; short reach; high flow count |
| ToR-to-Leaf | Packet switching | Mixed traffic types; congestion management needed |
| Leaf-to-Spine | Hybrid (OCS for elephant flows) | OCS handles large persistent flows; EPS handles mice flows |
| Spine Layer | OCS | Carries aggregated traffic; power and latency savings maximized |
| Inter-Pod / Inter-Cluster | OCS | Direct light paths; protocol transparency; dynamic reconfiguration |
| Scale-Across (Campus) | OCS + Coherent | OCS for reconfigurable topology; coherent for long-reach transport |
The pattern is clear: packet switching dominates at the edge, where per-packet flexibility and congestion management are essential. Optical circuit switching takes over in the core, where large flows dominate and power and latency efficiency matter most. Hybrid architectures blend the two, assigning each traffic type to the technology that handles it best.
14.Conclusion
Optical circuit switching and electronic packet switching represent two fundamentally different approaches to moving data through a network. Packet switching inspects, buffers, and forwards each packet individually, providing maximum flexibility at the cost of power, latency, and OEO conversion at every hop. Optical circuit switching establishes dedicated light paths, providing deterministic latency, dramatic power savings, and protocol transparency at the cost of reconfiguration granularity and control-plane complexity.
For AI data centers, the choice is not binary. Packet switching remains essential at the network edge, where per-packet processing and congestion management are required. Optical circuit switching excels in the core and spine layers, where elephant flows dominate and the power and latency savings are most impactful. Hybrid architectures that combine both technologies—using OCS for large, persistent flows and EPS for small, dynamic flows—represent the practical path forward.
The trajectory is unmistakable. As AI clusters scale from thousands to tens of thousands of GPUs, the power and latency overhead of packet-switched networks becomes unsustainable. OCS, proven at hyperscale by Google and increasingly adopted across the industry, offers a path to networks that are faster, cooler, and more scalable. The question is no longer whether optical switching will play a role in AI data centers, but how quickly it will displace electronic switching in the layers where it performs best.
 >

 >
 >
 >
 >
 >
 >
 >