TEL:+86 132 6656 7067


AI inference infrastructure serves trained models to applications, users, and automated systems. As deployment scales, GPU servers must exchange model data, coordinate processing, access memory and storage resources, and deliver responses within application latency targets. High-speed optical connectivity helps provide the bandwidth required to connect these resources across data center networks.
400G and 800G optical links support high-capacity connections between network switches and computing infrastructure. Their suitability depends on the inference workload, model architecture, server count, network topology, and required response time.
1. Optical Connectivity in AI Inference Networks
Inference networks connect GPU servers, switches, storage systems, and application infrastructure. Optical links are particularly useful for connections between racks and network layers where electrical cabling reach, port bandwidth, or physical routing becomes a constraint.
GPU server connectivity: Connects inference servers to high-speed network switches through compatible NICs and optical interfaces.
Scale-out networking: Connects multiple servers so model workloads can run across distributed computing resources.
Storage and data access: Provides bandwidth for model loading, datasets, logs, and other supporting services.
Cluster expansion: Connects additional racks and network domains as inference capacity grows.
Within a server or rack-scale system, dedicated GPU interconnects may handle high-bandwidth local communication. Optical connectivity typically becomes more relevant when traffic crosses server, rack, or network-domain boundaries.
2. Inference Traffic and Network Performance
Inference traffic differs from training traffic. Requests arrive from applications and generate responses, while distributed inference may also exchange intermediate activations, model parameters, or other data between GPUs and servers. Large language models can place particular demands on communication when model layers or processing stages are distributed across multiple devices.
The network must balance throughput with latency. High aggregate bandwidth helps serve concurrent requests, while congestion, excessive queueing, or inefficient routing can increase response times.
| Network Requirement | Impact on Inference | Design Priority |
|---|---|---|
| Bandwidth | Affects concurrent request handling and distributed model communication | Match link capacity to workload and expected traffic |
| Latency | Influences response time, particularly for interactive applications | Reduce unnecessary network hops and queueing |
| Congestion control | Competing traffic can create delays and inconsistent performance | Monitor utilization and manage traffic distribution |
| Availability | Network failures can interrupt inference services | Plan suitable redundancy and recovery procedures |
| Scalability | More GPUs and servers increase aggregate traffic demand | Allow capacity for future expansion |
3. 400G and 800G Optical Transceivers
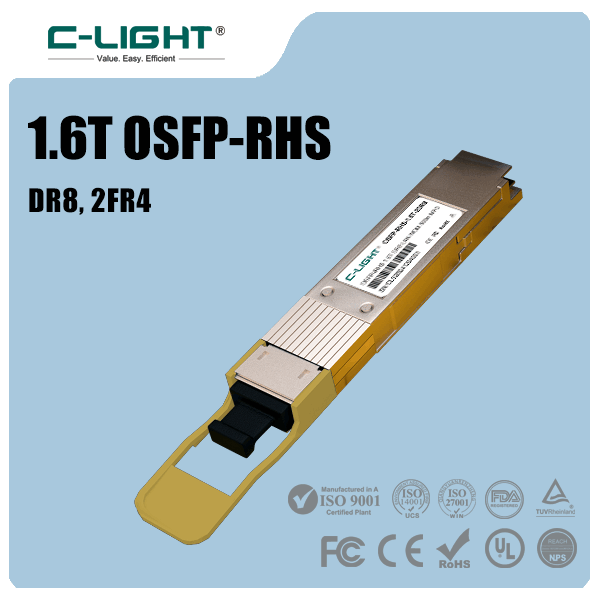
400G and 800G transceivers provide high-bandwidth interfaces for inference clusters. A 400G link can suit many server and switch connections, while 800G provides greater capacity per port where the host platform and workload justify it.
| Optical Interface | Potential Application | Selection Considerations |
|---|---|---|
| 400G | Server-to-switch links and data center fabric connections | Port availability, lane configuration, reach, and power |
| 800G | Higher-capacity inference fabrics and switch interconnections | Switch support, module cooling, optical interface, and traffic demand |
| DAC or AOC | Suitable short-distance server and rack connections | Distance, host compatibility, cable routing, and power requirements |
Higher-rate optics can increase bandwidth per port, but they do not automatically improve inference response times. Actual performance also depends on server configuration, GPU communication patterns, topology, switch capacity, and congestion management.
4. Fiber Type and Transmission Distance
The fiber type must match the optical transceiver and intended link distance. Multimode and single-mode fiber support different optical interfaces and reach classes.
Multimode fiber: OM3 and OM4 are commonly used for supported short-reach data center links.
Single-mode fiber: OS2 supports a wide range of optical applications, including links between racks, equipment rooms, and separate facilities.
Optical reach: Maximum distance depends on the transceiver standard, fiber specification, connector losses, and optical budget.
Before deployment, confirm the optical standard, wavelength, connector type, receive-power limits, and host compatibility. Connector cleanliness and correct fiber polarity are also important for stable high-speed operation.
5. Network Topology and Reliability
A well-designed inference network balances server-facing bandwidth, switch capacity, and uplink capacity. Leaf-spine architectures can provide scalable paths between racks, while suitable routing and congestion-management mechanisms help maintain consistent performance under changing traffic loads.
InfiniBand and Ethernet-based RoCEv2 are both used in AI infrastructure. The choice affects network configuration, congestion control, interoperability, and operational practices. Optical transceivers must match the selected network interface and equipment requirements.
For reliable operation, network teams should monitor link utilization, packet drops, errors, latency, and optical diagnostics. Redundant paths may also be necessary for production inference services where network interruptions could affect application availability.
6. Selecting Optical Connectivity for Inference
Optical design should begin with the workload and network architecture. Before selecting transceivers and fiber, evaluate:
Expected concurrent requests and aggregate traffic demand.
GPU and NIC bandwidth, switch capacity, and network oversubscription.
Required optical rate, reach, fiber type, connector, and link budget.
Transceiver power consumption, thermal limits, and host compatibility.
Latency targets, congestion management, redundancy, and future capacity growth.
Small inference deployments may operate efficiently with a relatively simple network, while larger distributed systems can need higher-capacity fabrics and more deliberate traffic management. Capacity planning should reflect the target workload rather than assuming that every inference deployment requires 800G connectivity.
7. Conclusion
Optical connectivity enables AI inference systems to connect GPU servers and network switches with high bandwidth across data center infrastructure. 400G and 800G transceivers provide options for scaling capacity, while multimode and single-mode fiber support different reach requirements.
Reliable inference performance depends on the complete system: optical links, NICs, switches, network topology, congestion control, and server architecture. Matching the transceiver and fiber infrastructure to actual workload requirements helps build scalable networks without adding unnecessary cost or complexity.
 >

 >
 >
 >
 >
 >
 >
 >