TEL:+86 132 6656 7067


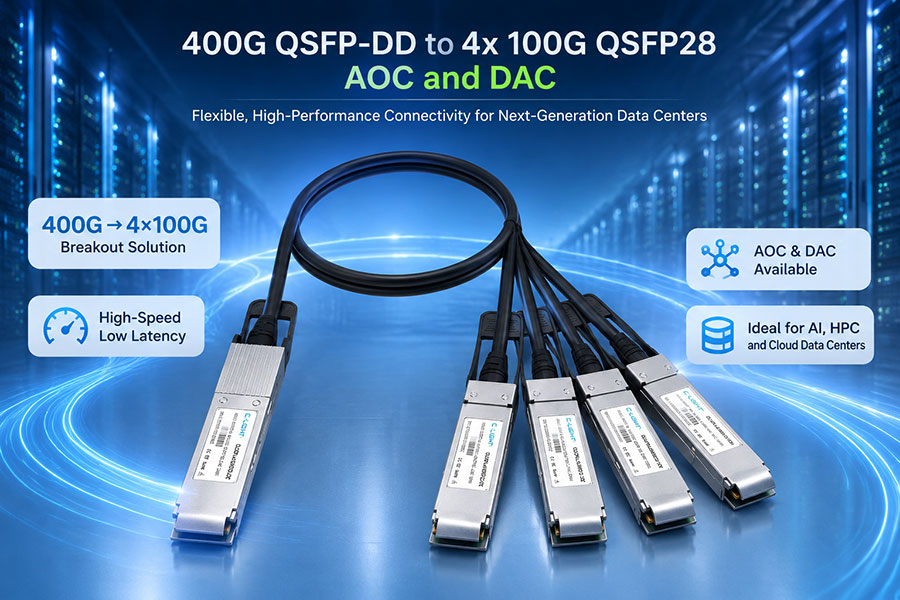
AI infrastructure is not a collection of GPU servers connected to an ordinary enterprise network. Distributed training and large-model inference require coordinated communication among accelerators, memory domains, compute nodes and storage systems. The optical network must move this traffic across physical distances while preserving sufficient bandwidth, predictable latency and room for expansion.
The architecture typically combines several communication domains: scale-up interconnects within tightly coupled accelerator systems, scale-out fabrics between servers and racks, and separate networks for storage, management and external services. Optical transceivers, direct-attach cables, active electrical cables, optical cables, switches and structured fiber each serve different positions in this architecture. The design challenge is choosing where each technology belongs rather than treating every connection as an interchangeable high-speed link.
1. The Main Network Domains in an AI Data Center
A large AI installation generally operates multiple networks with different performance and operational requirements. Their physical infrastructure may share a building or cable-management system, but their traffic patterns and failure consequences differ.
| Network domain | Primary function | Typical connectivity | Main design priority |
|---|---|---|---|
| Scale-up fabric | Connects closely coupled accelerators within a server or tightly integrated system | Specialized accelerator links and platform-specific interconnects; optical links may be used in some extended architectures | High local bandwidth, low latency and predictable peer-to-peer communication |
| Scale-out AI fabric | Connects GPU servers and racks for distributed training and inference | Ethernet or InfiniBand, high-speed switches and DAC, AEC, AOC or pluggable optics | Aggregate throughput, congestion control and scalable topology |
| Storage network | Moves datasets, checkpoints and model artifacts | Ethernet or storage-specific fabrics, depending on the platform | Sustained throughput, burst handling and workload isolation |
| Front-end service network | Connects inference services, clients and application infrastructure | Ethernet switches and optical or electrical uplinks | Availability, security and application-facing performance |
| Management network | Supports provisioning, monitoring and equipment administration | Dedicated or logically isolated Ethernet connectivity | Operational access, isolation and recovery |
Separating these domains helps prevent one traffic class from consuming resources needed by another. For example, checkpoint transfers can create substantial bursts, while distributed training may be sensitive to delays in collective communication. Network isolation, traffic engineering and appropriate capacity allocation help control these interactions.
2. Scale-Up and Scale-Out: Two Different Connectivity Problems
2.1 Scale-Up Inside an Accelerator System
Scale-up networking connects accelerators that cooperate closely on the same model or computational task. The architecture is often determined by the accelerator platform, including its supported links, switching structure, memory-sharing model and physical packaging.
Within a tightly integrated system, high-speed electrical interconnects can provide very high bandwidth over short distances. As the physical domain expands, electrical reach, cable routing and signal integrity can become limiting factors. Some systems may use optical technology for longer or denser connections, but optical transceivers are not automatically required for every scale-up link.
Scale-up design should be evaluated by the bandwidth available between accelerator pairs, not only by the sum of all advertised link rates. A topology with uneven paths can leave some communication patterns constrained even when its aggregate bandwidth appears high.
2.2 Scale-Out Between Servers and Racks
Scale-out fabrics connect separate compute nodes through Ethernet or InfiniBand switches. As the number of racks increases, the network must provide enough uplink capacity for traffic to cross rack boundaries without excessive contention.
High-speed optical links are especially useful when electrical cabling cannot meet the required reach, routing density or signal-integrity margin. Pluggable transceivers allow individual optical links to be selected according to bandwidth and distance, while AOCs provide integrated optical cabling for suitable fixed-reach connections.
3. A Typical Optical Scale-Out Architecture
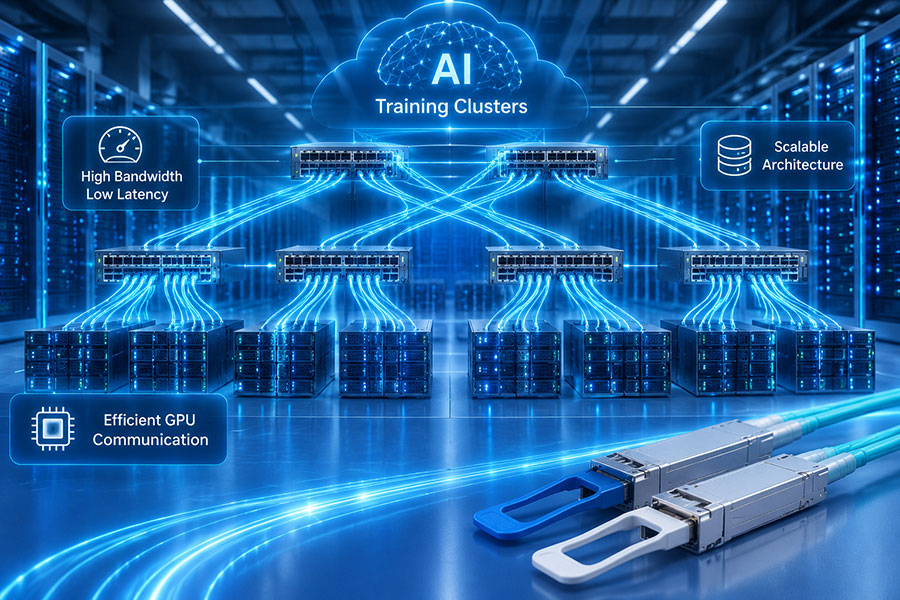
A common scale-out design uses a leaf-spine fabric. Leaf switches connect GPU servers, while spine switches provide paths between leaf switches. The number of uplinks and the capacity of each tier determine how much traffic can move between racks.
Rack A
Rack B
Rack C
Logical fabric view
Leaf switches aggregate server connections; spine switches provide inter-rack paths. Actual port counts, cabling and redundancy depend on the selected topology.
In this example, the leaf-to-spine links are natural candidates for optical connectivity when rack-to-rack distances or port density make copper impractical. The server-to-leaf connections may use DAC, AEC, AOC or discrete optical transceivers, depending on distance, interface support and the deployment's power budget.
A leaf-spine layout is not automatically non-blocking. If the total uplink bandwidth is lower than the endpoint capacity offered to it, the fabric is oversubscribed. Whether this becomes a performance problem depends on the workload's traffic matrix, congestion behavior and required communication completion time.
4. Selecting 400G, 800G and 1.6T Optical Links
Port rate affects how much bandwidth can be carried through a physical connection, but it also influences lane speed, module power, thermal density and the number of ports required on the switch. The appropriate generation depends on the host platform and the bandwidth target of each network tier.
| Port generation | Nominal aggregate rate | Architectural role | Key considerations |
|---|---|---|---|
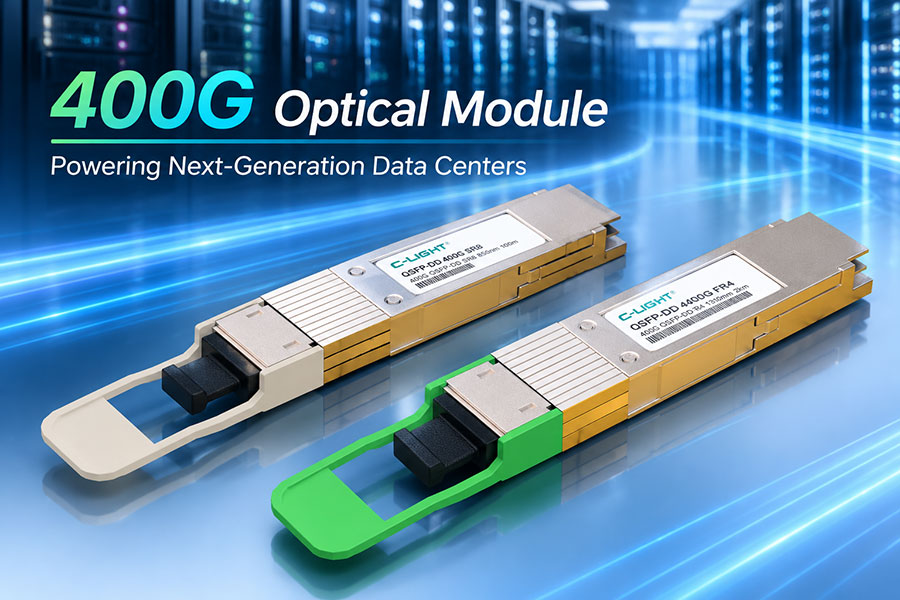
| 400G | 400 Gbit/s | Established high-speed links in data center and AI fabrics | Port count, reach, existing switch support and total link cost |
| 800G | 800 Gbit/s | Higher-bandwidth leaf-spine and large AI cluster connectivity | Host compatibility, module power, thermal limits and optical lane architecture |
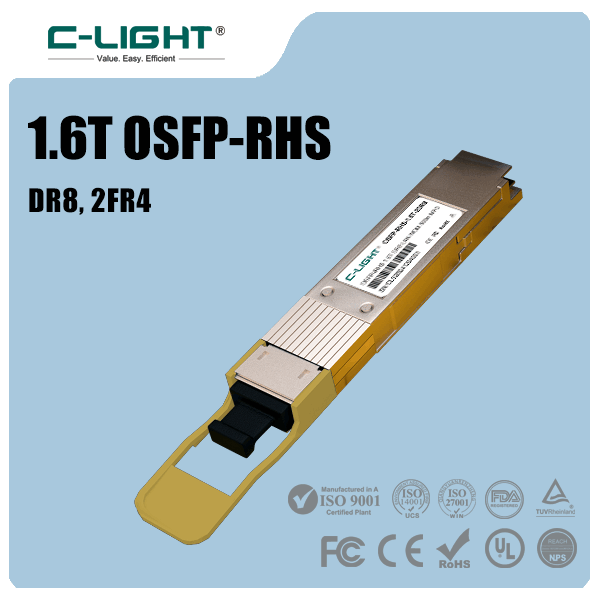
| 1.6T | 1.6 Tbit/s | Emerging high-density platforms requiring greater capacity per port | 200G-class lanes, signal integrity, ecosystem maturity and platform qualification |
Higher-rate links can reduce the number of physical ports needed to carry a target aggregate bandwidth. This may reduce cable count and simplify some parts of the fabric, but the result depends on switch radix, topology and the distribution of traffic. A faster port does not eliminate the need for sufficient total switching capacity.
The transition to 1.6T also involves more than doubling the optical data rate. Electrical interfaces, module thermal design, optical engines and host ASICs must support the new lane architecture. A planned upgrade should be based on qualified combinations of switches, transceivers and cabling rather than port-rate labels alone.
5. Choosing Between DAC, AEC, AOC and Pluggable Optics
The physical interconnect should be selected for the actual link distance and operating environment. Copper remains useful for short connections, while optical technology provides reach and routing flexibility across larger systems.
| Interconnect type | Best-fit role | Advantages | Limitations to consider |
|---|---|---|---|
| DAC | Short in-rack connections | Simple, cost-effective and typically low power | Reach, cable bulk and high-speed electrical channel limitations |
| AEC | Short electrical links needing active signal conditioning | Can extend practical copper reach in supported configurations | Additional power, cable electronics and compatibility requirements |
| AOC | Fixed-reach optical cable assemblies | Integrated optical ends and straightforward cabling | Endpoint optics are integrated into the cable assembly rather than separately replaceable |
| Pluggable optical transceivers | Switch-to-switch and other fiber links requiring flexible reach options | Replaceable modules, multiple reach choices and reusable fiber infrastructure | Module power, cooling, compatibility and optical budget requirements |
For example, two switches located in adjacent racks may support a qualified copper or AOC solution, while a longer inter-row or inter-room path may favor discrete optical transceivers and structured fiber. The final choice should account for the cable route, not just the straight-line distance between devices.
6. Fiber Plant, Reach and Connector Planning
The optical layer is only as reliable as the fiber infrastructure connecting its endpoints. Fiber type, connector format, polarity, insertion loss and cleanliness must match the transceiver's specifications and the intended link architecture.
6.1 Multimode and Single-Mode Fiber
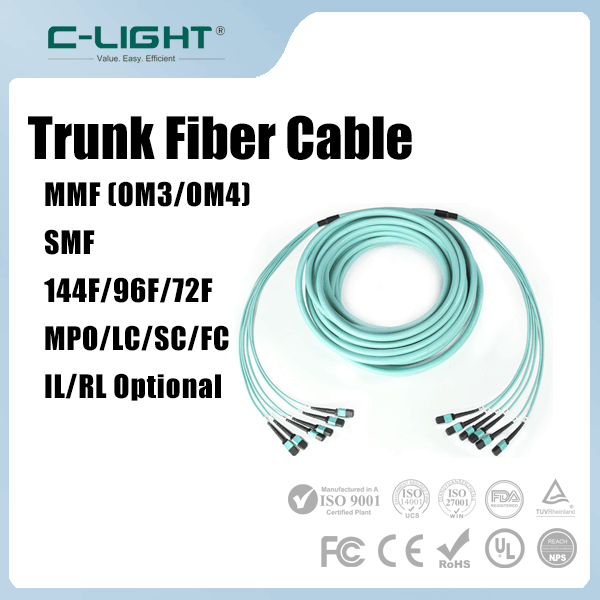
Multimode fiber is used for certain short-reach applications, while single-mode fiber supports a broad range of data center reaches. The choice depends on the optical module, wavelength, transmission distance and available fiber plant. A transceiver designed for one fiber type cannot be assumed to operate correctly over another.
6.2 MPO/MTP and Duplex Connectivity
Parallel-optics modules may use multi-fiber connectors, while duplex optical designs may use two-fiber connections. The exact connector and fiber arrangement depends on the module's transmit and receive architecture. Polarity and lane mapping must be correct at both ends for the link to establish successfully.
6.3 Optical Loss Budget
Every connector, splice and fiber segment contributes insertion loss. The total channel loss must remain within the optical link budget, with sufficient margin for manufacturing variation, aging and operational conditions. A link that works in a short bench test may fail after installation if the actual fiber path has excessive loss or contamination.
Structured cabling should be designed alongside switch placement and rack layout. Proper fiber routing, labeling, bend-radius control and connector inspection reduce installation errors and simplify later upgrades.
7. Ethernet, RoCEv2 and InfiniBand in AI Fabrics
The network protocol and the optical physical layer are separate design decisions. Ethernet and InfiniBand can both support high-speed AI communication, but their fabric management, congestion behavior and operational requirements differ.
7.1 Ethernet with RoCEv2
RoCEv2 carries RDMA traffic over IP and Ethernet. It can support low-latency, high-throughput communication, but performance depends on the complete system configuration. Congestion control, queue management, routing, adapter behavior and traffic engineering all influence results.
AI workloads can generate synchronized bursts across many links. Ethernet fabric design must account for these patterns rather than relying solely on average utilization. The appropriate congestion-management strategy depends on the platform and traffic mix.
7.2 InfiniBand
InfiniBand is widely used in high-performance computing and AI environments that require tightly integrated communication fabrics. It provides its own transport and fabric-management mechanisms, and its operational model differs from Ethernet deployments.
Neither protocol removes the need to size switch capacity, choose suitable optical reach and validate the end-to-end system. The selection should reflect application requirements, available software support, operations expertise, interoperability and cost.
8. Optical Circuit Switching and Alternative Fabric Designs
Traditional packet switches forward traffic through electronic switching fabrics. Optical circuit switching (OCS) provides another approach by establishing optical paths between selected endpoints or network segments. In suitable AI architectures, OCS can reconfigure connectivity to match changing communication demands.
Because an OCS can establish an optical path without performing conventional packet-by-packet electronic forwarding at that switching stage, it may reduce some intermediate switching overhead. However, it does not replace endpoint transceivers, the entire packet network or the need to manage traffic flows.
OCS is most useful when the workload and control system can benefit from reconfigurable optical paths. Its practical value depends on path setup behavior, traffic stability, topology, failure handling and integration with the packet fabric. It is not automatically the best choice for every AI cluster.
Other architectures may combine multiple fabrics, use dedicated communication planes or employ different topologies for different accelerator groups. The correct design follows the workload's communication structure rather than a single universal network template.
9. Power, Cooling and Port Density
As optical port rates increase, power and thermal management become architectural constraints. A rack containing many high-speed transceivers can produce substantial localized heat at the switch front panel, even when the overall cooling system has adequate capacity for the rack.
Power evaluation should include more than the optical modules. Host SerDes, retimers, switch ASICs, fans, pumps and facility cooling can all affect the energy required to move data. Lower module power is useful, but system-level efficiency depends on how the entire network is built and operated.
Compare energy per useful bit rather than relying only on the transceiver's nominal power.
Use copper where its reach and signal-integrity limits are appropriate, rather than deploying optics indiscriminately.
Choose optical reach and module architecture according to the actual fiber path and host requirements.
Validate thermal performance with representative port occupancy and sustained traffic.
Include cooling and maintenance requirements when comparing pluggable optics with more integrated architectures.
10. Building an Architecture That Can Scale
AI clusters often grow in stages as accelerator capacity, model size and traffic demand increase. An optical architecture should support those changes without requiring a complete redesign every time a new generation of network interface becomes available.
Map the communication domains: distinguish scale-up, scale-out, storage, service and management traffic.
Estimate bandwidth demand: account for endpoint rates, traffic patterns, oversubscription and expected cross-rack communication.
Choose switch topology: determine the required leaf and spine capacity, path diversity and failure tolerance.
Match physical links to distance: select DAC, AEC, AOC or optical transceivers according to channel requirements.
Qualify each connection: verify switch support, module coding, fiber type, connector mapping, link stability and diagnostic behavior.
Plan for future bandwidth: assess port density, fiber counts, rack space, thermal headroom and upgrade compatibility.
Validate under real workloads: measure throughput, latency, congestion and collective-operation performance at the intended scale.
A scalable architecture is not simply one that supports the highest available link rate. It is one that can add capacity while maintaining predictable communication, operational reliability and manageable power consumption.
11. Conclusion
AI data center optical network architecture connects accelerator systems, compute racks and storage infrastructure through multiple network domains. Scale-up links provide tightly coupled communication, while scale-out fabrics move traffic between servers and racks. High-speed optical transceivers, AOCs and structured fiber make it possible to extend bandwidth across the physical distances and port densities of large clusters.
400G, 800G and emerging 1.6T connectivity each have a role depending on platform capability and workload demand. The best architecture combines appropriate switch topology, protocol configuration, optical reach, connector design and thermal planning. Treating these elements as one system helps prevent expensive links from being undermined by congestion, poor fiber planning or compatibility problems.
12. Frequently Asked Questions
12.1 Why do AI data centers need specialized optical network architecture?
Distributed AI workloads generate substantial traffic between accelerators, servers and racks. A purpose-designed fabric provides the bandwidth, path capacity and operational controls needed to move that traffic without creating persistent communication bottlenecks.
12.2 Are optical transceivers used inside every GPU server?
No. Many short-distance scale-up connections use specialized electrical interconnects, and some server-to-switch connections use DAC or AEC. Optical transceivers are selected where the link distance, bandwidth, routing density and platform design justify optical connectivity.
12.3 Should an AI network use Ethernet or InfiniBand?
The choice depends on workload requirements, platform support, software ecosystem, operations expertise and cost. Both can support high-speed AI networking, but they differ in fabric architecture, congestion management and deployment practices.
12.4 What is the role of 800G and 1.6T optics?
They provide greater bandwidth per port, helping high-density fabrics carry more traffic without increasing port counts at the same rate. Their value depends on switch capacity, endpoint support, optical reach and power and thermal limits.
12.5 How does fiber selection affect AI network reliability?
Fiber type, connector format, polarity, insertion loss and cleanliness determine whether the optical channel meets the transceiver's requirements. Incorrect lane mapping or excessive loss can prevent links from establishing or reduce their operating margin.
Designing optical connectivity for AI clusters and high-density data centers?
Match transceiver speed, reach, fiber type and host compatibility to your switch topology and deployment requirements.
Contact C-LIGHT >

 >
 >
 >
 >
 >
 >
 >