TEL:+86 132 6656 7067


GPU-to-GPU interconnects provide the communication paths that allow graphics processing units to exchange data during AI training, high-performance computing (HPC), and other parallel workloads. As AI models grow in size, a single GPU may not provide enough compute capacity or memory for the entire workload. Multiple GPUs must cooperate, moving data between devices while minimizing communication overhead.
The performance of a multi-GPU system therefore depends not only on GPU processing power, but also on interconnect bandwidth, latency, topology, and software efficiency. Technologies such as NVLink, PCI Express (PCIe), and high-speed scale-out networking serve different roles within this communication architecture.
1. What Is a GPU-to-GPU Interconnect?
A GPU-to-GPU interconnect is a hardware and communication pathway that enables data exchange between GPUs. Depending on the system design, GPUs may communicate through a dedicated GPU fabric, PCIe switches, or a network interface connected to an external switch fabric.
These links carry data required for distributed computation, including intermediate tensors, activations, gradients, model parameters, and synchronization information. The communication pattern varies by workload and parallelization strategy.
Tensor parallelism: Splits portions of model computation across GPUs and often requires frequent communication between devices.
Data parallelism: Runs model replicas on different GPUs and exchanges gradients or parameter updates during training.
Pipeline parallelism: Distributes model stages across devices and transfers activations and gradients between stages.
Distributed inference: Uses multiple GPUs to serve large models or handle workloads that exceed the capacity of one device.
2. Main GPU Interconnect Technologies
NVLink
NVLink is a high-bandwidth interconnect technology used in supported NVIDIA GPU platforms. It provides GPU communication paths that can deliver higher aggregate bandwidth than a conventional PCIe connection in compatible system designs.
NVSwitch
NVSwitch is a switching technology for supported NVLink-based systems. It enables communication among multiple GPUs through a high-bandwidth fabric rather than relying only on direct point-to-point links.
PCI Express (PCIe)
PCIe is a standard high-speed interface used to connect GPUs with CPUs, memory-related devices, and other system components. Depending on platform topology, GPUs can communicate through PCIe links and switches.
Scale-Out Network
InfiniBand or Ethernet with RoCEv2 can connect GPU servers across a cluster. NICs or HCAs, network switches, and supported adapters provide the communication path between GPUs in different servers.
3. NVLink vs. PCIe vs. Scale-Out Networking
These technologies are not interchangeable. They operate at different levels of the computing infrastructure and are selected according to the required topology, bandwidth, distance, and system compatibility.
| Characteristic | NVLink / NVSwitch | PCIe | InfiniBand / Ethernet with RoCEv2 |
|---|---|---|---|
| Primary role | High-bandwidth GPU communication within supported systems | General-purpose system interconnect and device communication | Communication between servers and compute nodes |
| Typical deployment | Multi-GPU servers and supported GPU compute platforms | Server motherboards, PCIe switches, and accelerator platforms | Multi-server AI clusters and data center fabrics |
| Topology | Direct links or switched NVLink fabrics, depending on the platform | Point-to-point links through a PCIe hierarchy | NICs or HCAs connected through network switches |
| Distance scope | System-level links defined by the platform | System-level links defined by PCIe specifications and platform design | Within and between racks, depending on the network and physical media |
| Optical connectivity | Depends on the specific GPU platform and interconnect implementation | Standard PCIe links are electrical; optical extension requires purpose-built supported solutions | DAC, AOC, or optical transceivers and fiber can be used where supported |
| Key design factor | GPU topology and platform-supported bandwidth | PCIe generation, lane width, switch topology, and CPU connectivity | Network bandwidth, latency, congestion, adapter support, and fabric configuration |
Actual bandwidth depends on the GPU generation, number of links, link width, topology, and the vendor's specifications. Aggregate bandwidth figures should not be confused with the bandwidth available to a single GPU pair or application flow.
4. GPU-to-GPU Communication Inside a Server
Inside a multi-GPU server, communication may take place over NVLink, PCIe, or a combination of supported interconnects. The topology determines which GPUs have direct links, which traffic passes through switches, and how bandwidth is shared.
For example, a system with several GPUs connected through a high-bandwidth switched fabric can provide more communication paths than a design where all devices depend on a narrower shared route. However, the actual advantage depends on the supported GPU architecture, switch capacity, memory access behavior, and workload.
During model training, collective operations such as All-Reduce and All-Gather can generate significant traffic. Efficient communication paths help reduce synchronization overhead and improve the utilization of GPU compute resources.
5. GPU-to-GPU Communication Across Servers
When GPUs are distributed across different servers, communication generally passes through a network interface and the external network fabric. The data path may involve a GPU, a NIC or HCA, a leaf switch, one or more spine switches, and the destination server's adapter and GPU.
High-performance AI clusters commonly use InfiniBand or Ethernet with RoCEv2. Remote Direct Memory Access (RDMA), when supported and properly configured, can reduce CPU involvement and allow efficient data transfer between participating systems.
GPU Direct communication: Supported technologies can enable data movement between GPU memory and network adapters without requiring a conventional CPU-mediated copy for every transfer. Exact capabilities depend on hardware, drivers, and configuration.
Network topology: Leaf-spine designs provide scalable paths between racks, while uplink capacity and oversubscription influence cross-rack performance.
Congestion management: Multiple simultaneous GPU communication flows can compete for shared links. Appropriate routing and congestion-control configuration are essential.
Collective operations: The efficiency of All-Reduce and related operations depends on both network capabilities and the communication algorithms used by the software stack.
6. The Role of Optical Interconnects in Multi-GPU Clusters
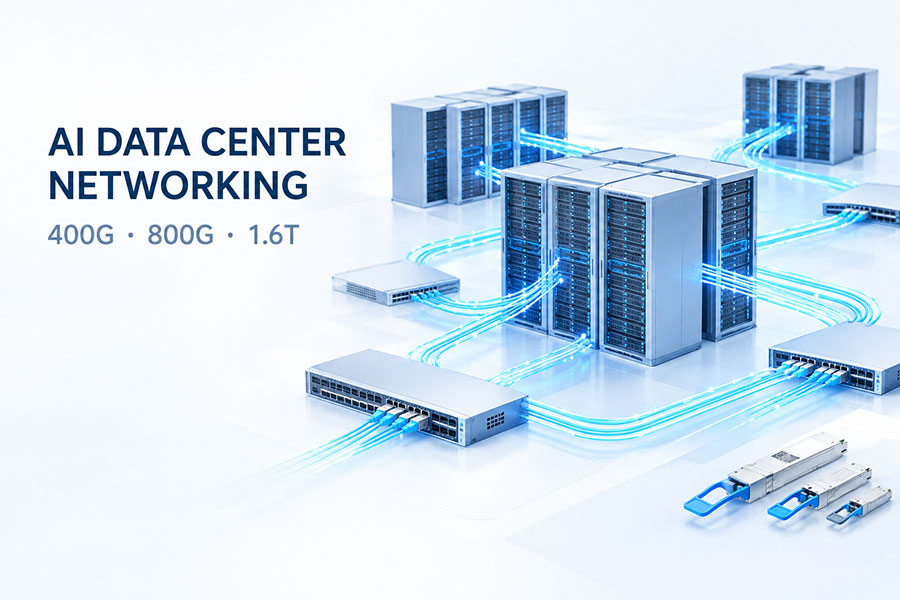
As GPU clusters expand beyond a single server or rack, the physical interconnect becomes an important part of network design. Optical links support high-speed communication over distances that may be impractical for conventional copper assemblies, while also offering flexible fiber routing between network devices.
| Connection Type | Typical Application | Key Considerations |
|---|---|---|
| DAC cable | Short links within a rack or between nearby devices | Supported reach, cable bulk, interface compatibility, and data rate |
| AOC | Integrated optical cabling for supported short-to-medium links | Specified reach, connector form factor, protocol, and host compatibility |
| Pluggable optical transceivers | High-speed switch-to-switch and switch-to-server network links | Port speed, optical reach, fiber type, wavelength, and connector configuration |
| Structured fiber cabling | Connections across racks, rows, or designated network distribution points | Fiber plant design, polarity, connector cleanliness, link budget, and serviceability |
Optical transceivers do not automatically replace a GPU's internal interconnect. In most deployments, pluggable optics connect the server's NIC or HCA to the network fabric, while GPU-to-GPU communication across servers is carried through the network protocol and adapter architecture.
7. What Determines GPU Interconnect Performance?
Interconnect performance should be evaluated at both the link level and the application level. A high theoretical link rate does not guarantee the same effective throughput for every GPU communication workload.
Bandwidth: Determines how much data can be transferred per unit of time. Check whether published figures describe per-direction, bidirectional, per-link, or aggregate bandwidth.
Latency: Affects the time required to initiate and complete communication, particularly for operations involving many synchronization steps.
Topology: Determines available communication paths, potential bottlenecks, and how bandwidth is shared between GPUs.
Memory transfer efficiency: Data placement, copy operations, and supported direct memory access capabilities influence effective throughput.
Congestion: Shared links and oversubscribed network paths can limit performance when many devices communicate concurrently.
Software stack: Drivers, communication libraries, collective algorithms, and application parallelization all affect results.
Reliability and monitoring: Link errors, retransmissions, configuration issues, and thermal constraints can affect sustained performance and availability.
8. Choosing an Interconnect for AI Infrastructure
Interconnect selection begins with the physical scope of the workload and the capabilities of the GPU platform. The following considerations help align the architecture with performance and deployment requirements.
Identify the communication domain. Determine whether GPUs communicate within one server, across a rack, or across multiple racks.
Check platform support. Verify GPU, CPU, motherboard, switch, NIC or HCA capabilities and supported interconnect configurations.
Estimate communication demand. Evaluate model parallelism, collective operations, expected traffic, and target cluster size.
Design the network fabric. Review switch capacity, uplink ratios, topology, routing, and congestion-management requirements.
Select the physical media. Match DAC, AOC, or optical transceivers and fiber to the link distance, data rate, and supported interfaces.
Validate end-to-end performance. Test link integrity, bandwidth, latency, collective communication, and representative AI workloads before scaling up.
9. Frequently Asked Questions
Q1: What is the difference between NVLink and PCIe?
Answer: NVLink is designed for high-bandwidth communication in supported GPU platforms, while PCIe is a general-purpose system interconnect used by GPUs and many other devices. Their bandwidth, topology, and capabilities depend on the implementation.
Q2: Do GPUs in different servers communicate through NVLink?
Answer: Standard multi-server communication typically uses a network fabric such as InfiniBand or Ethernet with RoCEv2. Specialized platform architectures may provide additional GPU interconnect capabilities, so the supported design must be verified for the specific system.
Q3: Why does GPU-to-GPU bandwidth matter for AI training?
Answer: Distributed training requires GPUs to exchange data and synchronize computation. Insufficient communication bandwidth or excessive latency can increase waiting time and reduce overall training efficiency.
Q4: Where are optical transceivers used in GPU clusters?
Answer: They are commonly used on supported NIC, HCA, and switch ports to connect servers and network devices across racks or other data center areas. They usually serve the scale-out network rather than replacing the GPU platform's internal interconnect.
Q5: Does a higher interconnect bandwidth always mean faster AI training?
Answer: Not necessarily. Training performance also depends on latency, topology, congestion, memory movement, communication algorithms, and the workload's compute-to-communication ratio.
Conclusion
GPU-to-GPU interconnects are fundamental to multi-GPU computing, enabling accelerators to exchange data and coordinate distributed workloads. NVLink and NVSwitch support high-bandwidth communication within compatible GPU platforms, PCIe provides a general-purpose system interconnect, and InfiniBand or Ethernet with RoCEv2 connects GPUs across servers.
As AI clusters scale, the internal GPU fabric and external network must be designed together. Appropriate switch capacity, low-congestion paths, compatible NICs or HCAs, and suitable DAC, AOC, or optical transceiver solutions help build a reliable infrastructure for distributed AI workloads.
Building high-speed connectivity for AI data centers?
Review optical transceiver data rates, supported interfaces, link distances, and host compatibility for your network deployment.
Contact C-LIGHT >

 >
 >
 >
 >
 >
 >
 >